model context protocol
Tung Bui Thanh (TungDaDev)11 mins read
# mcp là gì và tại sao nó quan trọng?
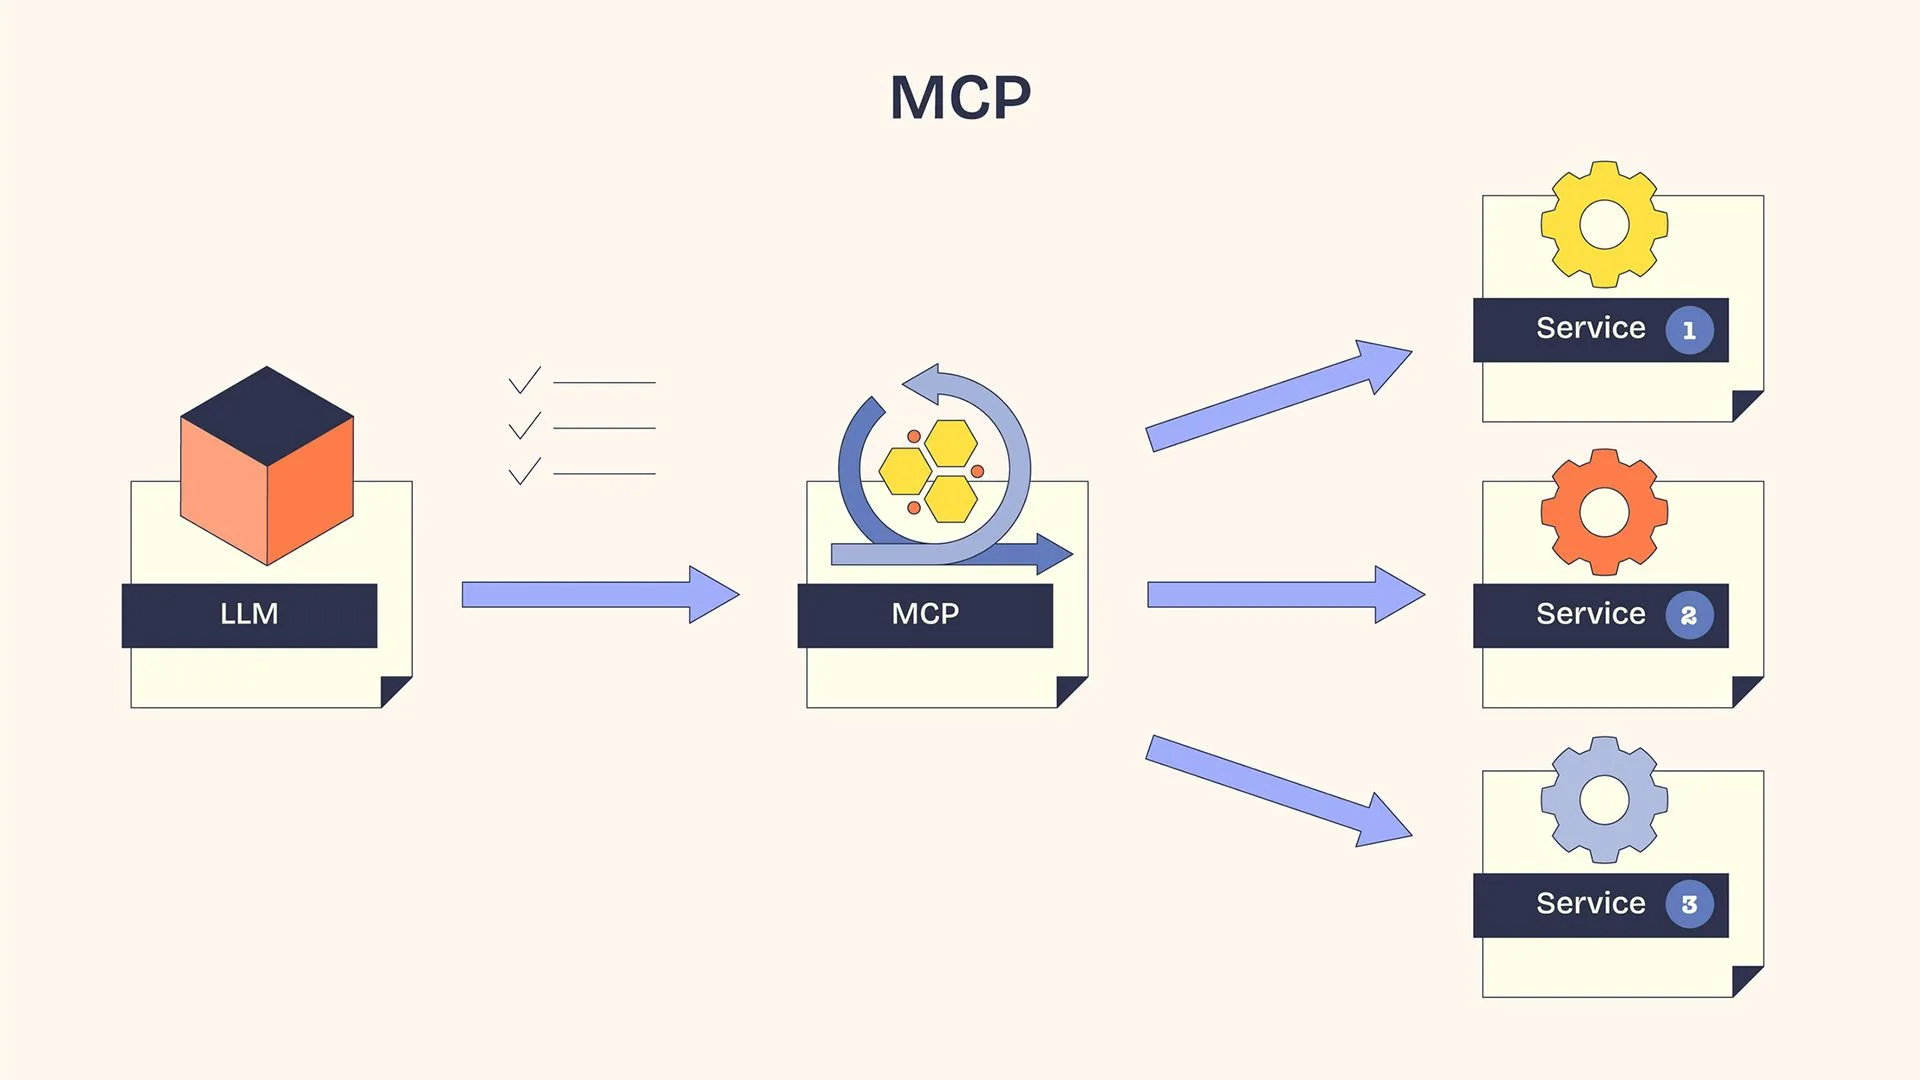
Bạn có Claude, GPT-4 hay Gemini, model nào cũng giỏi, nhưng đều bị nhốt trong sandbox. Muốn nó đọc Jira ticket? Viết code riêng. Muốn nó query database? Viết code riêng. Muốn nó tạo trang Confluence? Lại viết code riêng. Mỗi integration là một đống custom code, không tái sử dụng được, cũng chẳng theo chuẩn nào.
Model Context Protocol (MCP) sinh ra để xử lý chuyện này. Đây là một open standard (Anthropic khởi xướng từ tháng 11/2024, tới tháng 12/2025 thì chuyển cho Agentic AI Foundation thuộc Linux Foundation quản lý), quy định cách AI model kết nối với tool, nguồn dữ liệu và service bên ngoài theo cùng một protocol. Bên dưới, MCP là các message JSON-RPC 2.0 trao đổi giữa client và server.
So sánh cho dễ hình dung: HTTP chuẩn hoá cách browser nói chuyện với web server, còn MCP chuẩn hoá cách AI assistant nói chuyện với hệ thống bên ngoài. Hồi chưa có HTTP, mỗi cặp browser-server cần một protocol riêng. Chưa có MCP thì mỗi cặp AI-tool cần một integration riêng.
# trước mcp (n×m problem):
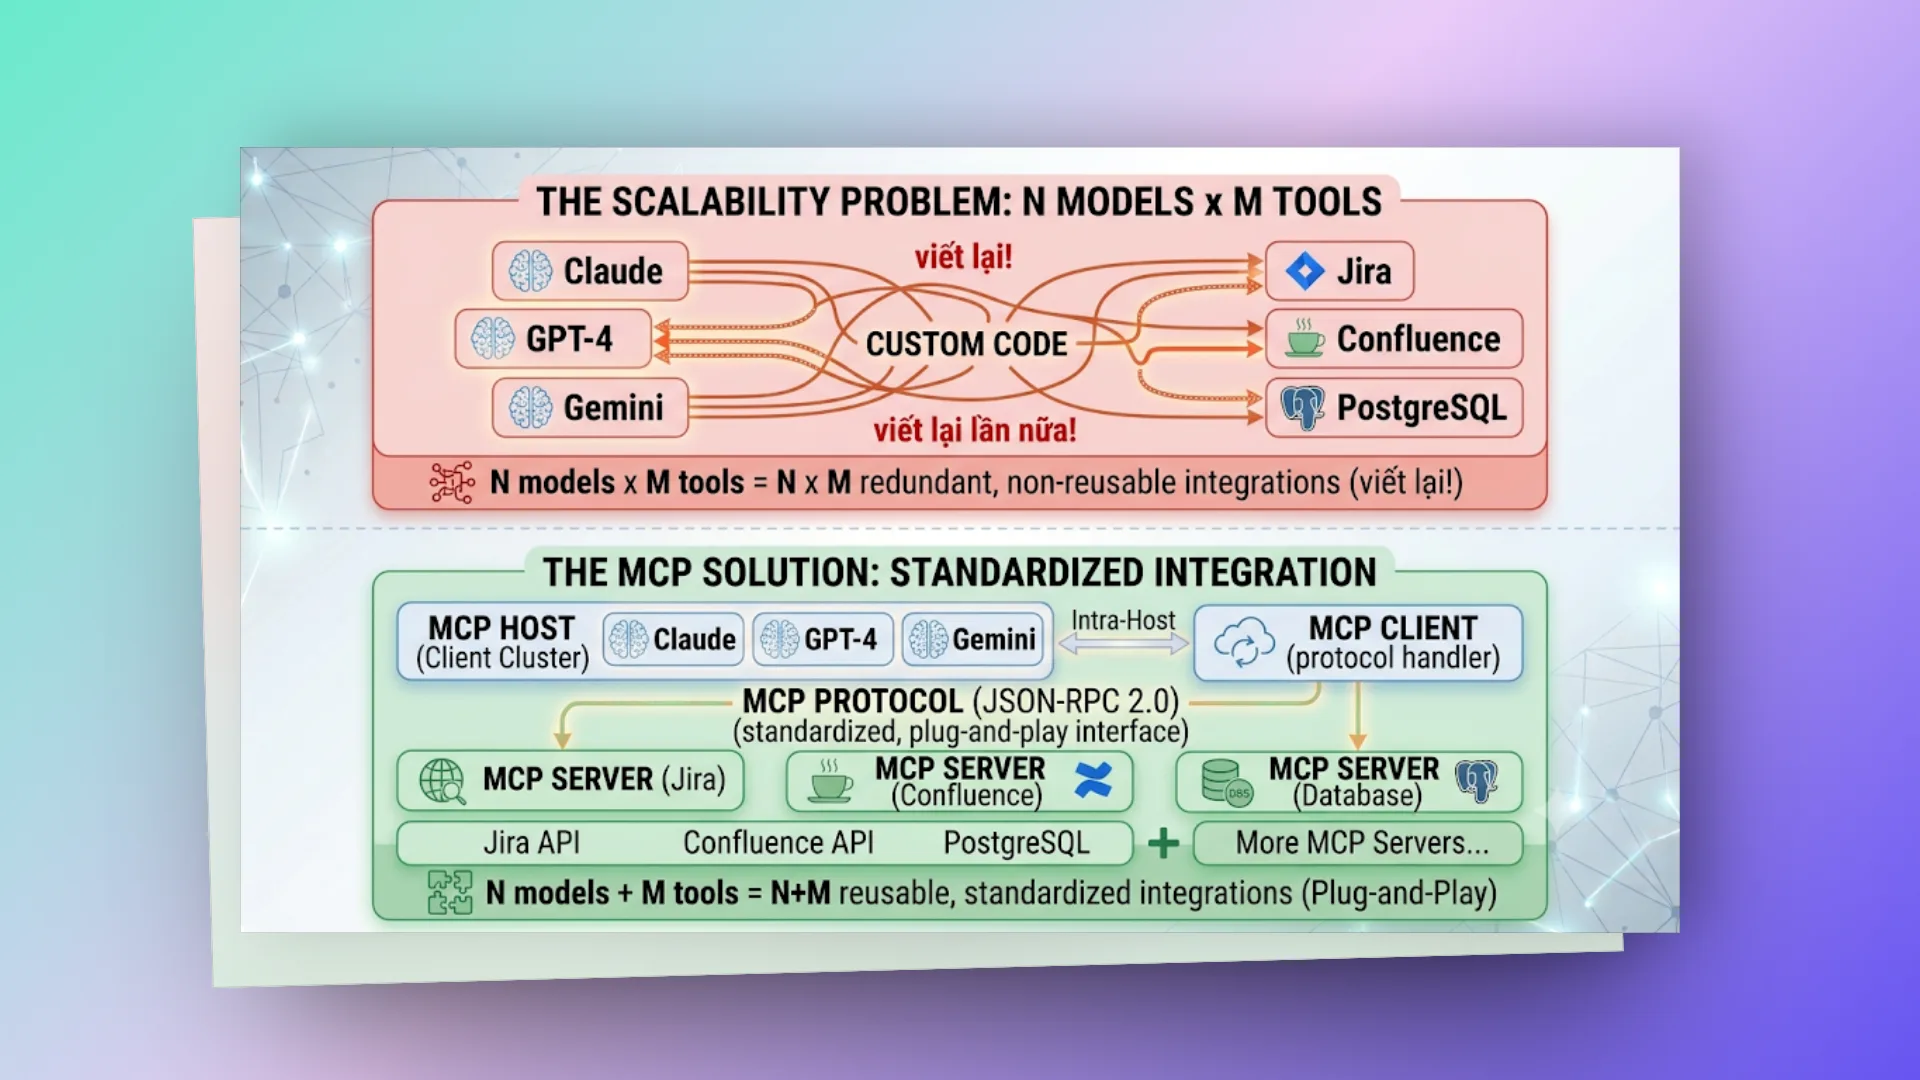
Claude ──── Custom code ──── Jira
Claude ──── Custom code ──── Confluence
Claude ──── Custom code ──── PostgreSQL
GPT-4 ──── Custom code ──── Jira (viết lại!)
GPT-4 ──── Custom code ──── Confluence (viết lại!)
Gemini ──── Custom code ──── Jira (viết lại lần nữa!)

N models × M tools = N×M integrations
# sau mcp (n+m solution):
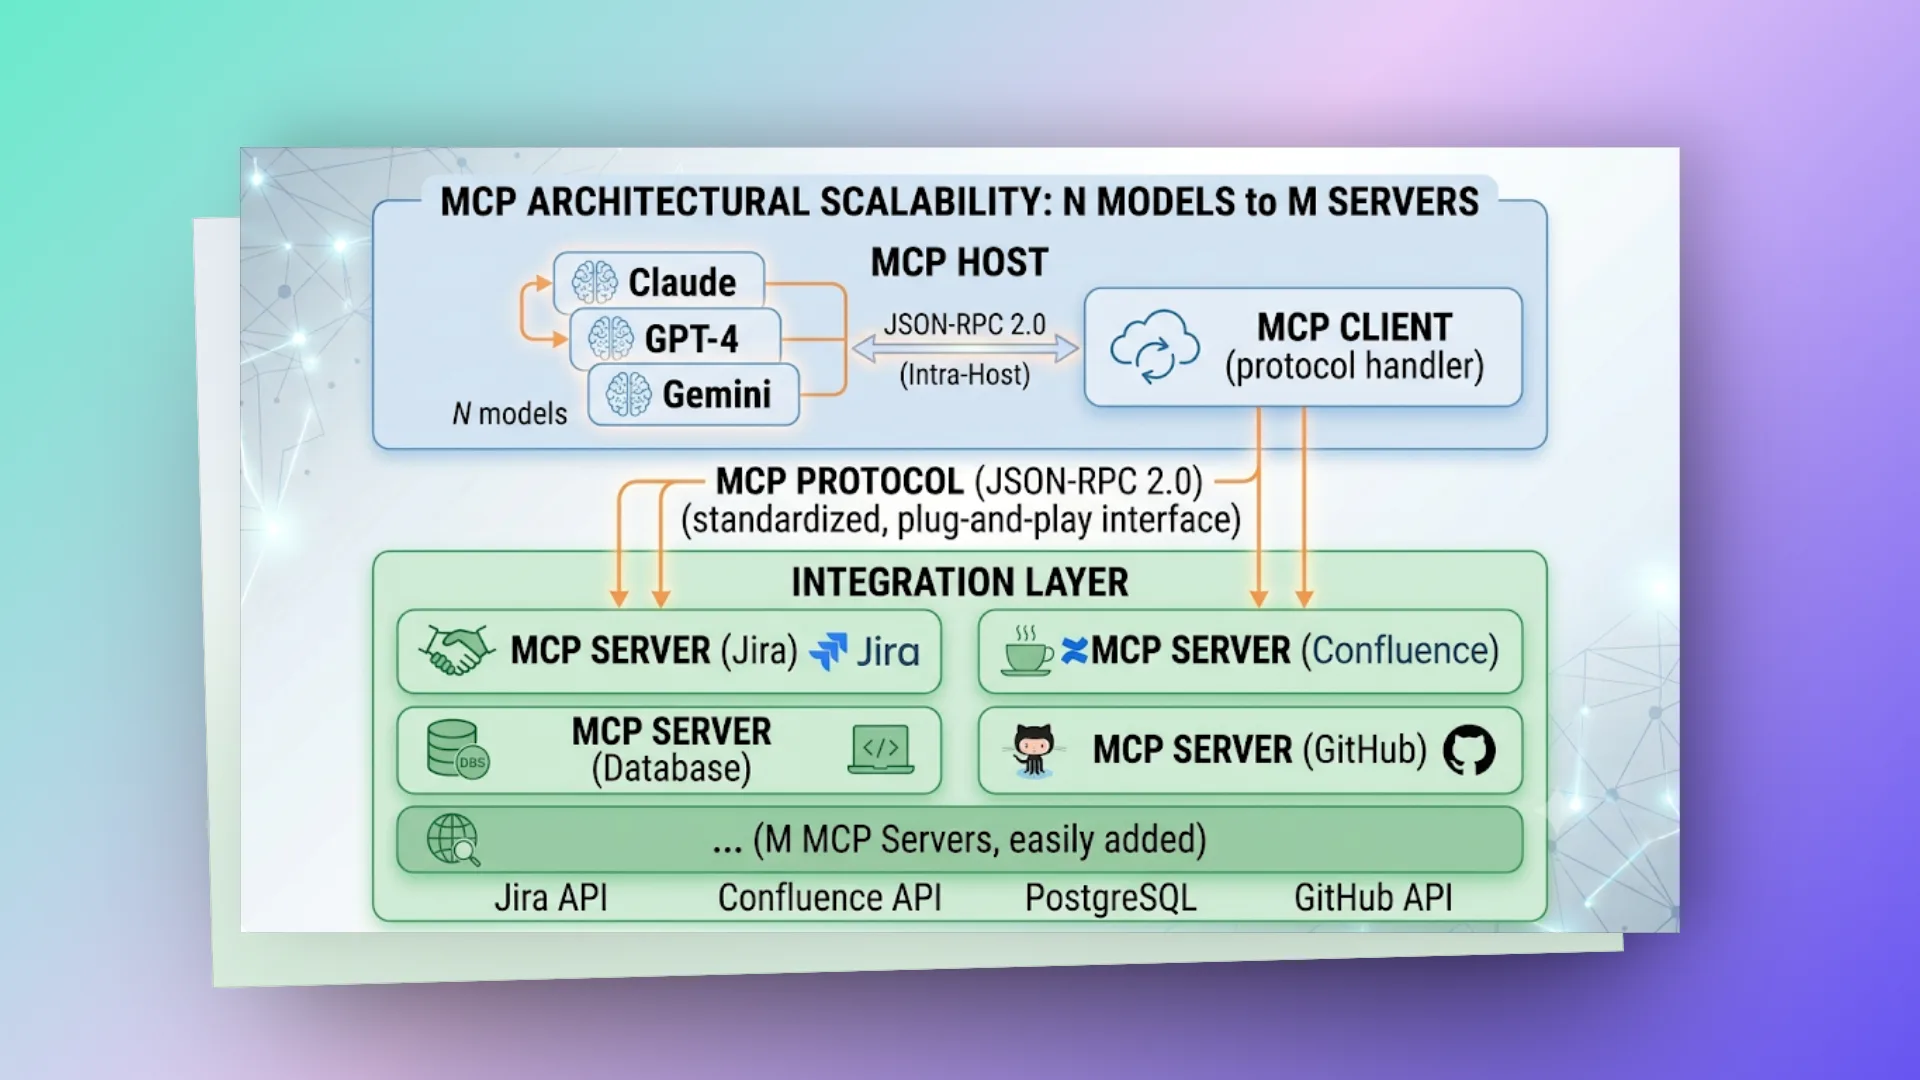
Điểm khác biệt nằm ở đây:
- Kiểu cũ (mỗi nơi tự tích hợp): Không có giao thức chung thì mỗi lần có model mới (ví dụ DeepSeek) hay tool mới cần đọc dữ liệu, dev lại phải viết adapter từ đầu cho từng cặp.
- Kiểu MCP (
N + M): Model nào đã implement phía client của MCP là "nói chuyện" được ngay với cả đống MCP Server có sẵn. Thêm gì cũng chỉ việc cắm vào là chạy (plug-and-play).
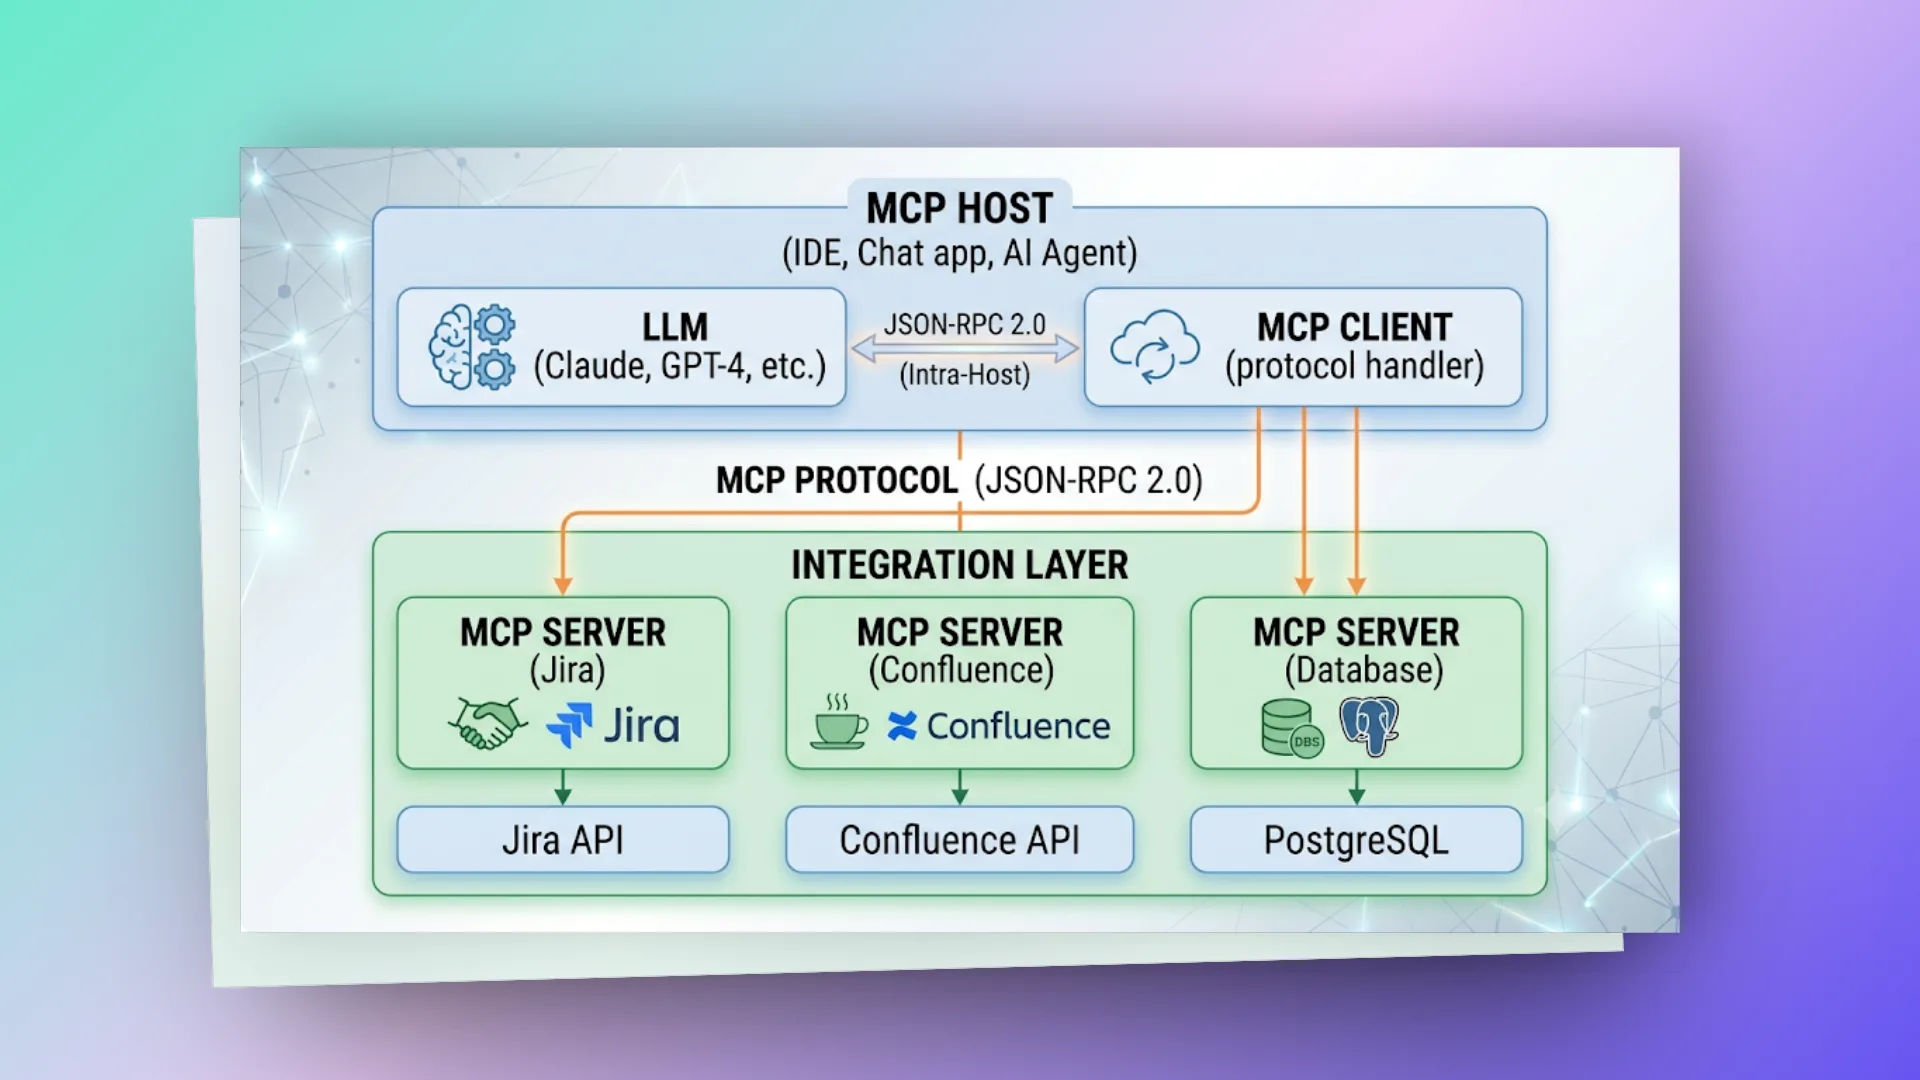
# architecture: client-server model
MCP theo kiến trúc client-server. Ứng dụng AI đóng vai MCP Client, còn hệ thống bên ngoài đưa chức năng của mình ra qua MCP Server.
# primitives của mcp:
| Primitive | Ai quyết định dùng | Mô tả | Ví dụ |
|---|---|---|---|
| Tools | Model | Việc AI làm được | create_issue, search_content |
| Resources | Ứng dụng (host) | Dữ liệu AI đọc được | file contents, database records |
| Prompts | User | Prompt template làm sẵn | "Summarize this page", "Review this PR" |
Cả ba đều do server cung cấp, client hỏi danh sách (tools/list, resources/list, prompts/list) rồi gọi khi cần. Khác nhau ở chỗ ai cầm quyền: tool do model tự chọn gọi, resource do ứng dụng quyết định nạp vào context, còn prompt thường hiện ra để user chủ động chọn (kiểu slash command).
# mcp server: build thế nào
MCP Server đưa các tool ra cho AI dùng. Mỗi tool gồm name, description (để AI biết lúc nào nên dùng), input schema (các parameter) và phần implementation.
# python mcp server (hay gặp nhất):
Đoạn code dưới đây dùng API low-level của Python SDK bản 1.x (pip install "mcp<2"), viết tay từng handler để thấy rõ protocol trông thế nào. jira_client là client Jira bạn tự viết, không có sẵn trong SDK. Từ bản 2.0, SDK đổi khá nhiều API (handler low-level truyền vào constructor của Server, field đổi sang snake_case như input_schema, FastMCP đổi tên thành MCPServer), nên với bản mới mình khuyên dùng MCPServer như ví dụ ngay sau.
# jira_mcp_server.py
import asyncio
from mcp.server import Server
from mcp.server.stdio import stdio_server
from mcp.types import Tool, TextContent

server = Server("jira-mcp")

@server.list_tools()
async def list_tools():
   return [
       Tool(
           name="get_issue",
           description="Get detailed information about a Jira issue by its key (e.g., PROJ-123)",
           inputSchema={
               "type": "object",
               "properties": {
                   "issue_key": {
                       "type": "string",
                       "description": "The Jira issue key (e.g., 'PROJ-123')"
                   }
               },
               "required": ["issue_key"]
           }
       ),
       Tool(
           name="create_issue",
           description="Create a new Jira issue in a project",
           inputSchema={
               "type": "object",
               "properties": {
                   "project_key": {"type": "string", "description": "Project key (e.g., 'PROJ')"},
                   "summary": {"type": "string", "description": "Issue title"},
                   "issue_type": {"type": "string", "description": "Type: Bug, Task, Story"},
                   "description": {"type": "string", "description": "Detailed description"}
               },
               "required": ["project_key", "summary", "issue_type"]
           }
       ),
       Tool(
           name="search_issues",
           description="Search Jira issues using JQL query",
           inputSchema={
               "type": "object",
               "properties": {
                   "jql": {"type": "string", "description": "JQL query string"},
                   "max_results": {"type": "integer", "default": 20}
               },
               "required": ["jql"]
           }
       )
   ]

@server.call_tool()
async def call_tool(name: str, arguments: dict):
   if name == "get_issue":
       issue = await jira_client.get_issue(arguments["issue_key"])
       return [TextContent(
           type="text",
           text=f"**{issue['key']}**: {issue['summary']}\n"
                f"Status: {issue['status']}\n"
                f"Assignee: {issue['assignee']}\n"
                f"Description: {issue['description']}"
       )]

   elif name == "create_issue":
       result = await jira_client.create_issue(
           project=arguments["project_key"],
           summary=arguments["summary"],
           issue_type=arguments["issue_type"],
           description=arguments.get("description", "")
       )
       return [TextContent(type="text", text=f"Created issue: {result['key']}")]

   elif name == "search_issues":
       issues = await jira_client.search(arguments["jql"], arguments.get("max_results", 20))
       formatted = "\n".join([f"- {i['key']}: {i['summary']} [{i['status']}]" for i in issues])
       return [TextContent(type="text", text=formatted)]

   raise ValueError(f"Unknown tool: {name}")


# Chạy server qua stdio
async def main():
   async with stdio_server() as (read_stream, write_stream):
       await server.run(read_stream, write_stream, server.create_initialization_options())

if __name__ == "__main__":
   asyncio.run(main())
Với SDK 2.x, phần lớn boilerplate ở trên biến mất: MCPServer tự sinh inputSchema từ type hint, lấy description từ docstring.
# jira_mcp_server.py (mcp 2.x)
from mcp.server.mcpserver import MCPServer

mcp = MCPServer("jira-mcp")

@mcp.tool()
async def get_issue(issue_key: str) -> str:
   """Get detailed information about a Jira issue by its key (e.g., PROJ-123)"""
   issue = await jira_client.get_issue(issue_key)
   return f"**{issue['key']}**: {issue['summary']}\nStatus: {issue['status']}"

@mcp.tool()
async def search_issues(jql: str, max_results: int = 20) -> str:
   """Search Jira issues using JQL query"""
   issues = await jira_client.search(jql, max_results)
   return "\n".join(f"- {i['key']}: {i['summary']} [{i['status']}]" for i in issues)

if __name__ == "__main__":
   mcp.run()  # mặc định transport stdio
# transport protocols
MCP hỗ trợ 2 kiểu transport:
1. stdio (Standard I/O) — cho local tools
  Host spawns server process, communicate qua stdin/stdout
  Fast, simple, no network overhead
  Use case: local file system, git, local database

2. Streamable HTTP — cho remote servers
  Client gửi JSON-RPC qua HTTP POST tới một endpoint duy nhất (vd /mcp),
  server trả JSON hoặc stream nhiều message qua SSE khi cần
  Network-ready, scalable, có auth (OAuth 2.1)
  Use case: cloud services, shared team tools, SaaS integrations
Bản spec đầu (11/2024) dùng "HTTP + SSE" với hai endpoint riêng. Từ bản spec 2025-03-26, kiểu này bị thay bằng Streamable HTTP và chỉ còn giữ để tương thích ngược, nên server mới thì nên làm Streamable HTTP. Nguồn: MCP spec: Transports.
# configuration (trong ide/ai tool):
Tên package dưới đây chỉ để minh hoạ cấu trúc file config, khi dùng thật hãy lấy đúng tên package/lệnh chạy từ trang của server đó. Cú pháp ${VAR} để đọc biến môi trường cũng tuỳ client có hỗ trợ hay không.
// .kiro/settings/mcp.json hoặc tương đương
{
  "mcpServers": {
    "jira": {
      "command": "uvx",
      "args": ["jira-mcp-server@latest"],
      "env": {
        "JIRA_URL": "https://your-company.atlassian.net",
        "JIRA_TOKEN": "${JIRA_API_TOKEN}"
      }
    },
    "confluence": {
      "command": "uvx",
      "args": ["confluence-mcp-server@latest"],
      "env": {
        "CONFLUENCE_URL": "https://your-company.atlassian.net/wiki",
        "CONFLUENCE_TOKEN": "${CONFLUENCE_TOKEN}"
      }
    },
    "postgres": {
      "command": "uvx",
      "args": ["postgres-mcp-server@latest"],
      "env": {
        "DATABASE_URL": "postgresql://user:pass@localhost:5432/mydb"
      }
    }
  }
}
# cách ai sử dụng mcp tools
Ví dụ user nhờ: "Tạo bug ticket cho lỗi login trên Jira project PORTAL"
User message: "Create a bug ticket for the login error in PORTAL project"
               │
               ▼
LLM reasoning: "User wants to create a Jira issue.
               I have tool 'create_issue' available.
               Project = PORTAL, type = Bug, summary about login error"
               │
               ▼
Tool call: create_issue({
   "project_key": "PORTAL",
   "summary": "Login error - users unable to authenticate",
   "issue_type": "Bug",
   "description": "Users reporting inability to login. Need investigation."
})
               │
               ▼
MCP Client → MCP Server (Jira) → Jira REST API → Create issue
               │
               ▼
Response: "Created issue: PORTAL-456"
               │
               ▼
LLM formats response: "Done! I've created PORTAL-456: 'Login error - users unable to authenticate' as a Bug in the PORTAL project."
Điểm cần nhớ: AI dựa vào description của tool để quyết định KHI NÀO dùng nó. Description viết tốt thì AI gọi đúng lúc. Viết ẩu thì AI gọi sai, hoặc chẳng thèm gọi.
# resources & prompts
# resources: dữ liệu ngữ cảnh
Resources cho AI đọc dữ liệu mà không cần "làm" gì. Tools là để thực thi một việc, còn resources chỉ để đọc.
@server.list_resources()
async def list_resources():
   return [
       Resource(
           uri="jira://project/PORTAL/issues",
           name="PORTAL Project Issues",
           description="All open issues in PORTAL project",
           mimeType="application/json"
       ),
       Resource(
           uri="confluence://space/ENG/pages",
           name="Engineering Space Pages",
           description="All pages in Engineering Confluence space"
       )
   ]

@server.read_resource()
async def read_resource(uri):
   # SDK truyền vào kiểu AnyUrl chứ không phải str, so sánh trực tiếp với chuỗi sẽ luôn False
   if str(uri) == "jira://project/PORTAL/issues":
       issues = await jira_client.get_open_issues("PORTAL")
       return formatted_issues(issues)
   raise ValueError(f"Unknown resource: {uri}")
# prompts: prompt template dùng lại được
Prompts là các chỉ dẫn soạn sẵn mà server đưa cho AI. User chọn một prompt, AI chạy nó cùng với ngữ cảnh hiện có.
@server.list_prompts()
async def list_prompts():
   return [
       Prompt(
           name="review-pr",
           description="Review a pull request for code quality and potential issues",
           arguments=[
               PromptArgument(name="pr_number", description="PR number to review", required=True)
           ]
       )
   ]

@server.get_prompt()
async def get_prompt(name: str, arguments: dict):
   if name == "review-pr":
       pr_data = await github_client.get_pr(arguments["pr_number"])
       return GetPromptResult(
           messages=[
               PromptMessage(
                   role="user",
                   content=TextContent(
                       type="text",
                       text=f"Review this PR for code quality:\n\n"
                            f"Title: {pr_data['title']}\n"
                            f"Files changed: {pr_data['files']}\n"
                            f"Diff:\n{pr_data['diff']}\n\n"
                            f"Focus on: security, performance, readability."
                   )
               )
           ]
       )
# security considerations
MCP mở cửa cho AI chạm vào hệ thống bên ngoài, nên bảo mật phải tính kỹ:
- Principle of least privilege: Server chỉ đưa ra những tool thật sự cần, đừng kiểu "admin, làm gì cũng được"
- Approval flows: IDE/Host có thể bắt user duyệt trước khi chạy tool (human-in-the-loop)
- Input validation: Server PHẢI validate mọi input từ AI (AI có thể hallucinate parameter)
- Secret management: Token để trong env var, không hardcode, không ghi ra log
- Rate limiting: Không cho AI spam API
- Audit logging: Log lại mọi tool call để phục vụ compliance
import re

@server.call_tool()
async def call_tool(name: str, arguments: dict):
   # Always validate
   if name == "delete_issue":
       # str không có method .match(), phải dùng module re
       if not re.fullmatch(r"[A-Z][A-Z0-9]*-\d+", arguments.get("issue_key", "")):
           raise ValueError("Invalid issue key format")

       # Log for audit (user lấy từ thông tin xác thực của request, tuỳ cách bạn làm auth)
       logger.info(f"TOOL_CALL: delete_issue | key={arguments['issue_key']} | user={current_user}")

       # Execute
       await jira_client.delete_issue(arguments["issue_key"])
       return [TextContent(type="text", text=f"Deleted {arguments['issue_key']}")]
# mcp ecosystem (2025-2026)
| Category | Servers available |
|---|---|
| Code & Dev | GitHub, GitLab, Git (local), Linear |
| Documentation | Confluence, Notion, Google Docs |
| Project Management | Jira, Asana, Monday.com |
| Database | PostgreSQL, MongoDB, SQLite, Supabase |
| Communication | Slack, Discord, Email |
| Cloud | AWS, GCP, Azure (documentation + services) |
| File System | Local filesystem, S3, Google Drive |
| Monitoring | Datadog, PagerDuty, Grafana |
| Custom | Any REST API (build your own in hours) |
# khi nào build mcp server?
Nên build MCP Server khi:
- Team có internal tool mà AI cần truy cập (JIRA nội bộ, dashboard tự làm)
- Có workflow lặp đi lặp lại muốn AI làm thay (tạo ticket, cập nhật docs, deploy)
- Muốn AI assistant hiểu ngữ cảnh riêng của mình (đọc codebase, query DB nội bộ)
Không cần build khi:
- Cộng đồng đã có server rồi (xem MCP Registry chính thức hoặc các danh mục cộng đồng như mcp.so)
- Chỉ cần 1-2 lần gọi API đơn giản (prompt engineering là đủ)
- Chính sách bảo mật không cho AI đụng vào hệ thống đó
Ước lượng công sức: MCP server đơn giản (3-5 tool, 1 nguồn dữ liệu) mất khoảng 1-2 ngày. Server phức tạp (auth, pagination, error handling, test) thì cỡ 1 tuần.
Chỉ là những ghi chép cá nhân với hy vọng mang lại chút giá trị. Nếu thấy hữu ích, đừng ngại chia sẻ cho bạn bè & đồng nghiệp nhé!
Happy coding 😎 👍🏻 🚀 🔥.