prometheus
Tung Bui Thanh (TungDaDev)11 mins read
Hệ thống phân tán dù thiết kế Clean Architecture tới đâu mà thiếu giám sát thì cũng như tàu ngầm chạy trong đêm tối. Không đo được thì không tối ưu được.
Bài này không dừng ở "How-to" mà đi vào "Why" và "How it works under the hood" của Prometheus, mảnh ghép gần như không thể thiếu trong Observability của hệ thống Backend hiện đại.
# bản chất
Điểm khác biệt lớn nhất của Prometheus so với InfluxDB hay Datadog nằm ở cách thu thập dữ liệu: Pull-based (Scrape) thay vì Push-based.
Service không phải chủ động gửi dữ liệu đi. Nó chỉ cần expose trạng thái qua một HTTP endpoint (thường là /metrics). Prometheus sẽ định kỳ tới lấy về và lưu vào Time-Series Database (TSDB) nội bộ.
Độc lập & Tối giản: target không bị ràng buộc với hệ thống giám sát. Prometheus sập thì target vẫn chạy bình thường, không tốn tài nguyên retry push data.
Dễ Debug: chỉ cần mở trình duyệt vào /metrics của service là thấy nó đang expose những gì, không cần công cụ gì thêm.
# kiến trúc
Prometheus có luồng xử lý khá rõ ràng, mỗi thành phần lo một việc:
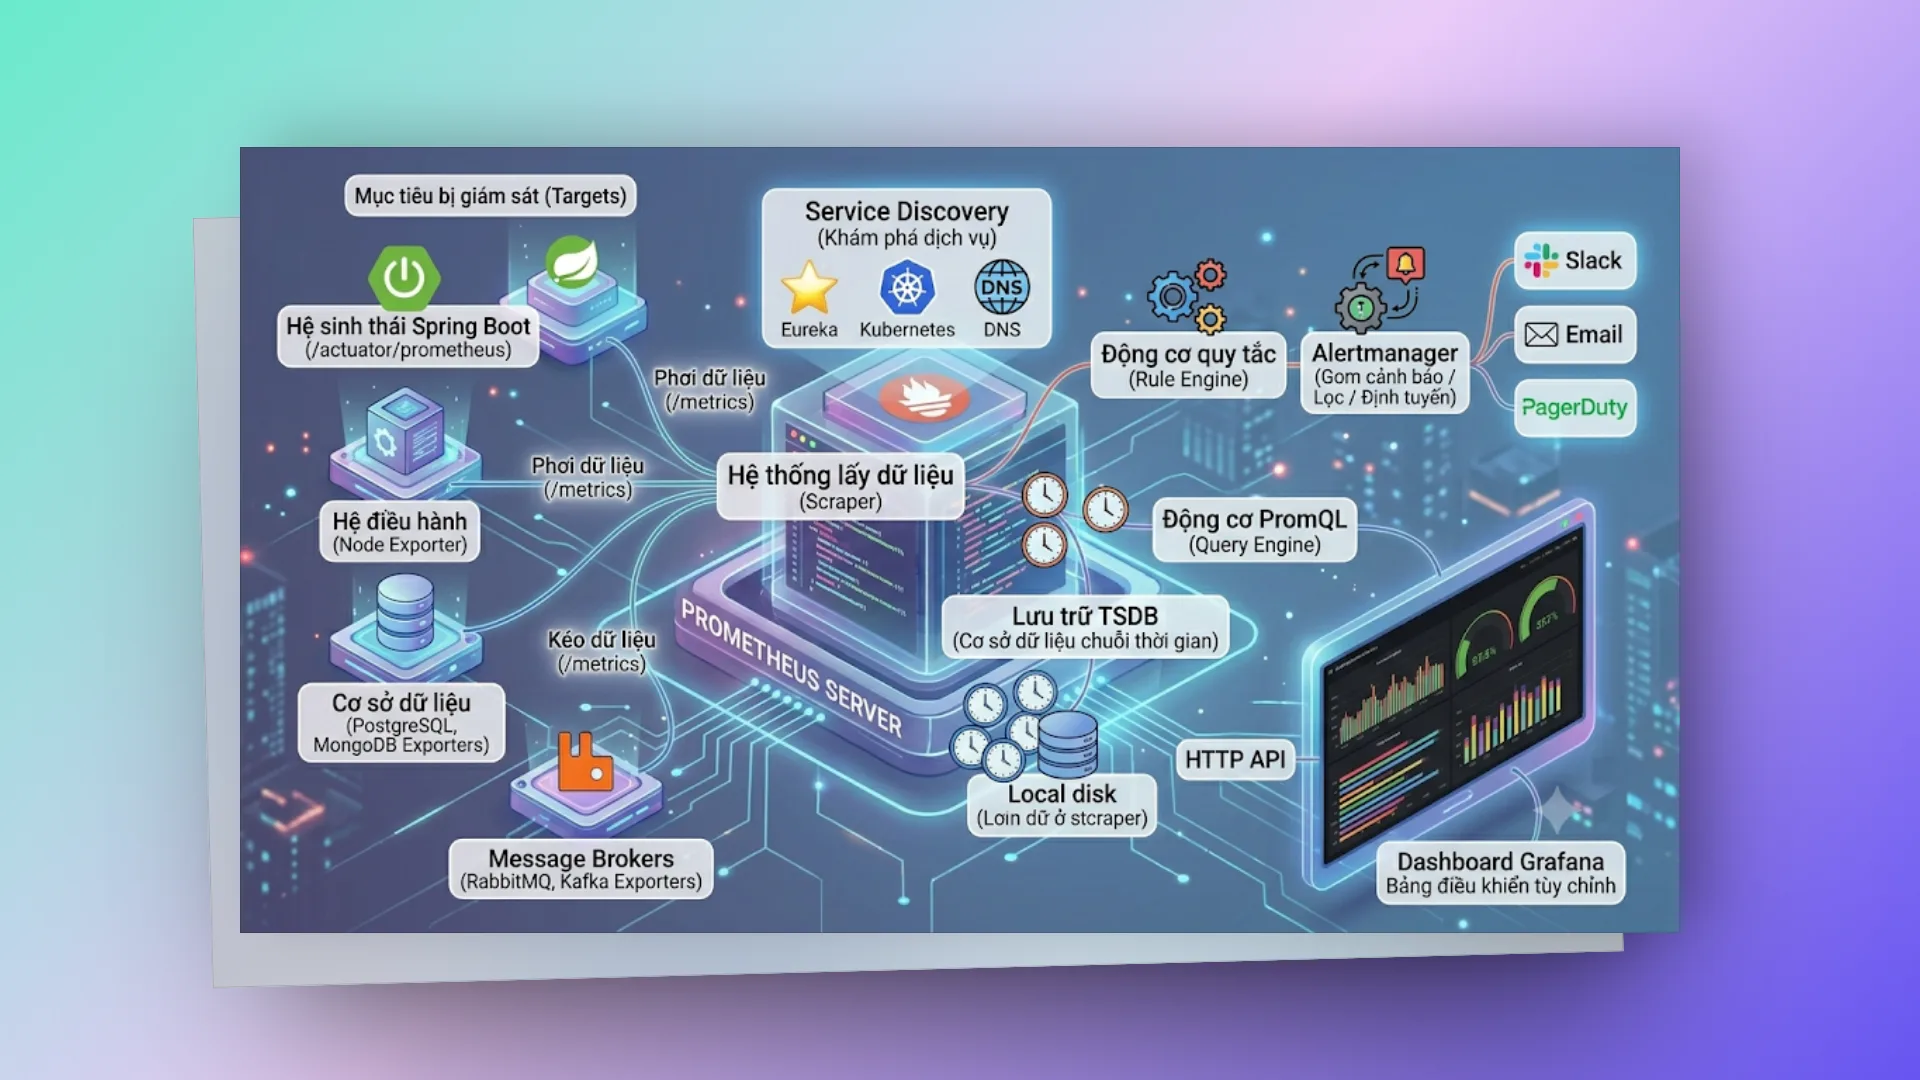
Sơ đồ trên mô tả luồng hoạt động chính của Prometheus server, gồm các thành phần sau:
- Service Discovery: tự động tìm các service mới và đang chạy để Prometheus theo dõi. Nó lấy danh sách target từ các nguồn như Eureka, Kubernetes (K8s), DNS,... và liên tục cập nhật. Nhờ vậy Prometheus tự co giãn theo khi service được thêm hoặc bỏ khỏi hệ thống.
- Scrape Targets: dựa trên danh sách từ Service Discovery, Prometheus kéo (pull) metrics (/metrics) từ các target. Quá trình này gọi là "scrape". Mỗi target cần expose một HTTP endpoint (thường là /metrics) theo định dạng Prometheus hiểu được. Metrics được kéo định kỳ, và đây là điểm quan trọng: Prometheus chủ động đi lấy dữ liệu, không chờ service gửi tới.
- TSDB Storage: metrics thu được sẽ lưu vào Time-Series Database (TSDB) trên đĩa cục bộ. TSDB được tối ưu cho dữ liệu chuỗi thời gian, giúp Prometheus lưu và truy vấn lượng lớn metrics hiệu quả. Dữ liệu được lưu thành các điểm liên tiếp theo thời gian cho từng metric.
- PromQL Engine: thành phần xử lý truy vấn. Bạn viết các truy vấn phức tạp bằng PromQL (Prometheus Query Language) để phân tích và lấy thông tin từ TSDB, ví dụ tính tỷ lệ, tổng hợp theo thời gian, phát hiện bất thường, v.v.
- HTTP API: giao diện HTTP để các công cụ bên ngoài làm việc với Prometheus. Các ứng dụng khác (như Grafana hoặc dashboard tự viết) query TSDB qua PromQL Engine và nhận kết quả dạng JSON.
- Grafana / Custom Dashboards: các công cụ trực quan hóa dữ liệu. Chúng kết nối HTTP API của Prometheus để query metrics và hiển thị thành biểu đồ, bảng điều khiển trên trình duyệt. Grafana là công cụ phổ biến nhất để vẽ dữ liệu từ Prometheus.
- Rule Engine & Alertmanager:
Rule Engine: Prometheus liên tục đánh giá các rule (khai báo trong file cấu hình). Có hai loại:
- Recording rule: tạo metric mới dựa trên PromQL (ví dụ: tính tỷ lệ lỗi).
- Alerting rule: định nghĩa điều kiện cảnh báo dựa trên metrics (ví dụ: cảnh báo nếu tỷ lệ lỗi > 5%).
Alertmanager: khi một alerting rule thỏa điều kiện, Prometheus gửi cảnh báo tới Alertmanager. Đây là một thành phần riêng, lo việc gửi cảnh báo. Nó có thể:
- Gom cảnh báo: nhóm các cảnh báo liên quan để giảm nhiễu.
- Lọc cảnh báo: chặn hoặc bỏ qua các cảnh báo không cần thiết.
- Định tuyến cảnh báo: gửi tới các kênh khác nhau như Slack, Email, PagerDuty, v.v. dựa trên cấu hình.
# metric types
Dữ liệu thô mà không phân loại đúng thì vô nghĩa. Prometheus định nghĩa 4 kiểu metric cơ bản, và backend engineer nào cũng nên hiểu rõ chúng.
| Type | Mô tả | Ví dụ |
|---|---|---|
| Counter | Chỉ tăng (reset khi restart) | Total requests, errors, bytes sent |
| Gauge | Tăng/giảm tự do | Temperature, memory usage, queue size |
| Histogram | Distribution (buckets) | Request duration, response size |
| Summary | Distribution (quantiles, client-side) | Request duration (ít dùng) |
# counter
Con số raw tự nó vô nghĩa (ví dụ: service báo đã nhận 1 triệu requests kể từ lúc start). Cái cần quan tâm là tốc độ thay đổi, nên luôn dùng hàm rate() hoặc increase(). Hai hàm này còn tự xử lý chuyện counter bị reset về 0 khi service restart: thấy giá trị tụt xuống thì Prometheus hiểu là reset chứ không tính thành số âm.
http_requests_total{method="GET", status="200"} 1234
http_requests_total{method="POST", status="500"} 5
Luôn dùng rate() hoặc increase() với counter (raw value vô nghĩa):
rate(http_requests_total[5m]) # requests/sec averaged over 5min# gauge
jvm_memory_used_bytes{area="heap"} 524288000
process_cpu_usage 0.45
Dùng trực tiếp hoặc với avg_over_time():
jvm_memory_used_bytes{area="heap"}
avg_over_time(process_cpu_usage[5m])
# histogram
Với Histogram, giá trị lớn nhất là tính được bách phân vị (Percentiles) để đảm bảo SLA. Các bucket là cộng dồn: le="0.1" nghĩa là có 800 request mất ≤ 100ms (đã gồm cả 500 request ≤ 50ms):
http_request_duration_seconds_bucket{le="0.01"} 100
http_request_duration_seconds_bucket{le="0.05"} 500
http_request_duration_seconds_bucket{le="0.1"}  800
http_request_duration_seconds_bucket{le="0.5"}  950
http_request_duration_seconds_bucket{le="1.0"}  990
http_request_duration_seconds_bucket{le="+Inf"} 1000
http_request_duration_seconds_sum 45.2
http_request_duration_seconds_count 1000
Tính percentiles:
histogram_quantile(0.95, rate(http_request_duration_seconds_bucket[5m]))Kết quả là ước lượng: Prometheus chỉ biết có bao nhiêu request rơi vào mỗi bucket, nên nó nội suy tuyến tính bên trong bucket chứa p95. Bucket càng thưa thì sai số càng lớn, vì vậy nên đặt ranh giới bucket sát các ngưỡng SLA bạn quan tâm. Bù lại, histogram cộng gộp được giữa nhiều instance (sum by (le)), còn quantile của Summary tính sẵn ở client thì không cộng hay lấy trung bình được.
# promql essentials
# instant vector (current values)
http_requests_total{job="order-service"}
up{job="order-service"}  # 1 = healthy, 0 = down
# range vector (values over time)
http_requests_total{job="order-service"}[5m] # last 5 minutes of samples# functions
# Rate (per-second average over range)
rate(http_requests_total[5m])

# Increase (total increase over range)
increase(http_requests_total[1h])

# Aggregation
sum(rate(http_requests_total[5m])) by (method)
avg(process_cpu_usage) by (instance)
max(jvm_memory_used_bytes) by (application)
count(up == 1) by (job)

# Percentiles
histogram_quantile(0.99, sum(rate(http_request_duration_seconds_bucket[5m])) by (le))

# Comparison
http_requests_total > 1000
rate(http_requests_total{status=~"5.."}[5m]) > 0.1

# Math
sum(rate(http_requests_total{status=~"5.."}[5m]))
/ sum(rate(http_requests_total[5m])) * 100  # error percentage

# Prediction
predict_linear(node_filesystem_free_bytes[1h], 4*3600)  # predict 4h from now
# spring boot integration (micrometer)
Khi đưa Prometheus vào Java/Spring Boot, Micrometer đóng vai "facade" (giống SLF4J cho logging): code chỉ gọi API của Micrometer, còn đẩy sang Prometheus, Datadog hay backend nào là do registry bạn thêm vào.
# dependencies
<dependency>
   <groupId>io.micrometer</groupId>
   <artifactId>micrometer-registry-prometheus</artifactId>
</dependency>
<dependency>
   <groupId>org.springframework.boot</groupId>
   <artifactId>spring-boot-starter-actuator</artifactId>
</dependency>
# config
Cấu hình tối giản (application.yml):
management:
  endpoints:
    web:
      exposure:
        include: health, prometheus
  metrics:
    tags:
      application: ${spring.application.name}
    distribution:
      percentiles-histogram:
        http.server.requests: true # Bật tính năng chia bucket cho HTTP requests
      slo: # tên cũ "sla" đã deprecated từ Spring Boot 2.3, bản mới chỉ còn "slo"
        http.server.requests: 50ms, 100ms, 200ms, 500ms, 1s # Định hình các bucket theo SLA kỳ vọng
# custom metrics
Đừng chỉ giám sát hạ tầng. Hãy đưa metrics vào sâu trong core domain để đo được tình hình của business.
@Service
public class OrderService {

   private final Counter orderCounter;
   private final Timer orderProcessingTimer;
   private final Gauge activeOrdersGauge;
   private final AtomicInteger activeOrders = new AtomicInteger(); // Gauge chỉ giữ weak reference, nên giữ object này làm field

   public OrderService(MeterRegistry registry) {
       // Đặt tên metrics theo chuẩn phân cấp rõ ràng
       this.orderCounter = Counter.builder("orders.created.total")
           .description("Total orders created")
           .tag("type", "standard")
           .register(registry);

       this.orderProcessingTimer = Timer.builder("orders.processing.duration")
           .description("Order processing time")
           .publishPercentiles(0.5, 0.95, 0.99) // p95/p99 tính sẵn ở client, KHÔNG gộp được giữa các instance
           .publishPercentileHistogram()         // nên bật thêm để tính quantile bằng histogram_quantile() phía Prometheus
           .register(registry);

       this.activeOrdersGauge = Gauge.builder("orders.active.count",
               activeOrders, AtomicInteger::get)
           .description("Currently active orders")
           .register(registry);
   }

   public Order createOrder(OrderRequest request) {
       return orderProcessingTimer.record(() -> {
           Order order = processOrder(request);
           orderCounter.increment();
           return order;
       });
   }
}
# prometheus config
Hệ thống alert tốt không phải hệ thống réo chuông liên tục trên Slack. Alert fatigue làm kỹ sư mất phản xạ. Nên làm tối giản: chỉ báo khi thực sự cần.
- Alert trên Symptoms, không phải Causes: cảnh báo khi "Tỉ lệ lỗi thanh toán vượt quá 5%" thay vì "CPU của DB node 3 tăng cao". End-user không quan tâm CPU, họ quan tâm giao dịch có bị thất bại hay không.
- Tránh cảnh báo thoáng qua (Flapping): luôn dùng mệnh đề for để lỗi phải kéo dài đủ lâu mới báo.
# prometheus.yml
global:
  scrape_interval: 15s
  evaluation_interval: 15s

scrape_configs:
  - job_name: 'spring-boot-apps'
    metrics_path: /actuator/prometheus
    eureka_sd_configs:
      - server: http://discovery:8087/discovery/eureka
    relabel_configs:
      - source_labels: [__meta_eureka_app_name]
        target_label: application
      # Nếu instance khai báo management port riêng trong metadata thì scrape port đó
      - source_labels: [__address__, __meta_eureka_app_instance_metadata_management_port]
        action: replace
        regex: ([^:]+)(?::\d+)?;(\d+)
        replacement: $1:$2
        target_label: __address__

  - job_name: 'node-exporter'
    static_configs:
      - targets: ['node-exporter:9100']

  - job_name: 'postgres-exporter'
    static_configs:
      - targets: ['postgres-exporter:9187']
# alerting rules
# alert-rules.yml
groups:
  - name: service-alerts
    rules:
      - alert: HighErrorRate
        expr: sum(rate(http_server_requests_seconds_count{status=~"5.."}[5m])) by (application) / sum(rate(http_server_requests_seconds_count[5m])) by (application) > 0.05
        for: 5m
        labels:
          severity: critical
        annotations:
          summary: 'High error rate on {{ $labels.application }}'
          description: 'Error rate is {{ $value | humanizePercentage }}'

      - alert: HighLatency
        expr: histogram_quantile(0.95, sum(rate(http_server_requests_seconds_bucket[5m])) by (le, application)) > 2
        for: 5m
        labels:
          severity: warning
        annotations:
          summary: 'High p95 latency on {{ $labels.application }}'

      - alert: ServiceDown
        expr: up == 0
        for: 1m
        labels:
          severity: critical
        annotations:
          summary: '{{ $labels.job }} is down'

      - alert: HighMemoryUsage
        expr: sum by (application, instance) (jvm_memory_used_bytes{area="heap"}) / sum by (application, instance) (jvm_memory_max_bytes{area="heap"}) > 0.9
        for: 5m
        labels:
          severity: warning
        annotations:
          summary: 'High heap usage on {{ $labels.application }}'
# alertmanager
# alertmanager.yml
route:
  receiver: 'slack-critical'
  group_by: ['alertname', 'application']
  group_wait: 30s
  group_interval: 5m
  repeat_interval: 4h
  routes:
    - matchers: ['severity="critical"'] # "match:" kiểu cũ đã deprecated từ Alertmanager 0.22
      receiver: 'slack-critical'
    - matchers: ['severity="warning"']
      receiver: 'slack-warning'

receivers:
  - name: 'slack-critical'
    slack_configs:
      - channel: '#alerts-critical'
        send_resolved: true
        title: '{{ .GroupLabels.alertname }}'
        text: '{{ range .Alerts }}{{ .Annotations.description }}{{ end }}'

  - name: 'slack-warning'
    slack_configs:
      - channel: '#alerts-warning'
        send_resolved: true
# key metrics to monitor (spring boot)
# Service health
up{application="order-service"}

# Request rate
sum(rate(http_server_requests_seconds_count{application="order-service"}[5m])) by (method, uri)

# Error rate
sum(rate(http_server_requests_seconds_count{application="order-service", status=~"5.."}[5m]))

# Latency percentiles
histogram_quantile(0.95, sum(rate(http_server_requests_seconds_bucket{application="order-service"}[5m])) by (le))

# JVM
jvm_memory_used_bytes{application="order-service", area="heap"}
jvm_gc_pause_seconds_sum
jvm_threads_live_threads

# Connection pools
hikaricp_connections_active{pool="HikariPool-1"}
hikaricp_connections_pending{pool="HikariPool-1"}

# RabbitMQ consumer
rabbitmq_consumed_total
spring_rabbitmq_listener_seconds_count
# storage & retention
# Command line flags
--storage.tsdb.retention.time=30d    # keep 30 days
--storage.tsdb.retention.size=50GB   # or max 50GB
--storage.tsdb.path=/prometheus/data
Long-term storage: Thanos, Cortex (hoặc Grafana Mimir, bản fork tiếp nối Cortex), hay bất kỳ hệ nào nhận Prometheus remote write.
# best practices
Để hệ thống giám sát không thành gánh nặng cho chính hạ tầng, nhớ mấy điểm sau:
- Quản lý Label Cardinality: đừng ném dữ liệu unique cao (như user_id, email, request_id) vào label của Prometheus. Mỗi tổ hợp giá trị label là một time series riêng, và series đang hoạt động được giữ trong RAM (head block). Một metric có 3 label, mỗi label 100 giá trị là có thể lên 1 triệu series. Bùng nổ kiểu này sẽ làm TSDB cạn RAM và crash. Với Spring Boot, cẩn thận cả tag
uricủa metrichttp.client.requests: gọi RestTemplate/WebClient bằng URL nối chuỗi ("/users/" + id) thay vì URI template ("/users/{id}") thì mỗi id thành một giá trị label. - Chu kỳ Scrape hợp lý: 15s đến 30s là phổ biến. Đừng set 1s chỉ vì muốn biểu đồ chạy "mượt".
- Cửa sổ tính Rate: Time Window truyền vào hàm rate() (ví dụ [5m]) nên lớn hơn scrape_interval ít nhất 4 lần. rate() cần tối thiểu 2 sample trong cửa sổ; cửa sổ quá sát thì chỉ một lần scrape lỡ là biểu đồ đứt.
- Lưu trữ dài hạn: Prometheus sinh ra để giữ data ngắn hạn (local disk). Đừng bắt nó ôm dữ liệu cả năm. Cần historical data cho report thì đẩy ra ngoài bằng Remote Write tới Thanos, Cortex hoặc VictoriaMetrics.
Bước tiếp theo nên làm: dựng thử stack Prometheus + Grafana bằng Docker Compose, trỏ vào một service Spring Boot, rồi viết vài alert rule ở trên và cố tình làm service lỗi để xem alert có bắn đúng lúc không.
Chỉ là những ghi chép cá nhân với hy vọng mang lại chút giá trị. Nếu thấy hữu ích, đừng ngại chia sẻ cho bạn bè & đồng nghiệp nhé!
Happy coding 😎 👍🏻 🚀 🔥.