logback & mdc in spring
Tung Bui Thanh (TungDaDev)36 mins read
A practical guide to building observable microservices: the patterns that work, the traps teams fall into, and the fixes that held up in production.
# introduction: the log that told me nothing
It's 2 AM and PagerDuty just woke you up. The e-commerce platform is dropping orders. You SSH into the production box, tail the logs, and get this:
2024-03-15 02:01:33.421 ERROR PaymentService - Payment processing failed
2024-03-15 02:01:33.422 ERROR OrderService - Order creation failed
2024-03-15 02:01:33.423 WARN  InventoryService - Stock check timeout
2024-03-15 02:01:33.424 ERROR PaymentService - Payment processing failed
2024-03-15 02:01:33.425 ERROR OrderService - Order creation failed
Which payment failure caused which order failure? Which user got hit? Is the inventory timeout related to the payment error, or is it a different request altogether? No idea. The logs are technically correct and practically useless.
That's what logging looks like in a distributed system with no correlation between log lines. MDC (Mapped Diagnostic Context) and distributed tracing exist to fix exactly this.
Below is what I've picked up building observable Spring Boot microservices, starting from MDC basics and ending with a distributed tracing setup you can run in production. None of it is theory: every pattern here has run in systems serving millions of requests a day.
# understanding the problem space
# why traditional logging breaks in microservices
In a monolith, a request lives inside one process. Thread-based logging works fine and the logs make sense. In microservices, things change:
- One user action can fan out to 5, 10, even 20 services
- Each service has its own log stream
- Requests run concurrently, so log lines from different requests get mixed together
- Async processing (message queues, event-driven flows) breaks the straight-line flow
- With auto-scaling, logs for one service are spread over several instances
Without correlation, debugging turns into grep, squinting at timestamps, and guessing.
# what we need
For microservices, a decent observability setup needs:
- Request Correlation: every log line from one request shares a unique ID
- Cross-Service Tracing: that ID travels across service boundaries
- Causal Ordering: you can rebuild the exact path a request took
- Low Overhead: tracing shouldn't noticeably slow things down
- Transparency: application code doesn't have to pass trace IDs around by hand
That's the job MDC and distributed tracing take on.
# logback fundamentals, beyond the basics
# why logback?
Spring Boot ships Logback as the default logging framework, and it's a sensible default:
- Performance: much faster than Log4j 1.x and in the same league as Log4j2 (each project publishes benchmarks where it comes out ahead; for a typical service the difference won't be your bottleneck)
- Native SLF4J support: no bridge needed
- Flexible configuration: conditional processing, filters, reloading config on the fly
- First-class MDC support: it's part of the core
# logback architecture in 60 seconds
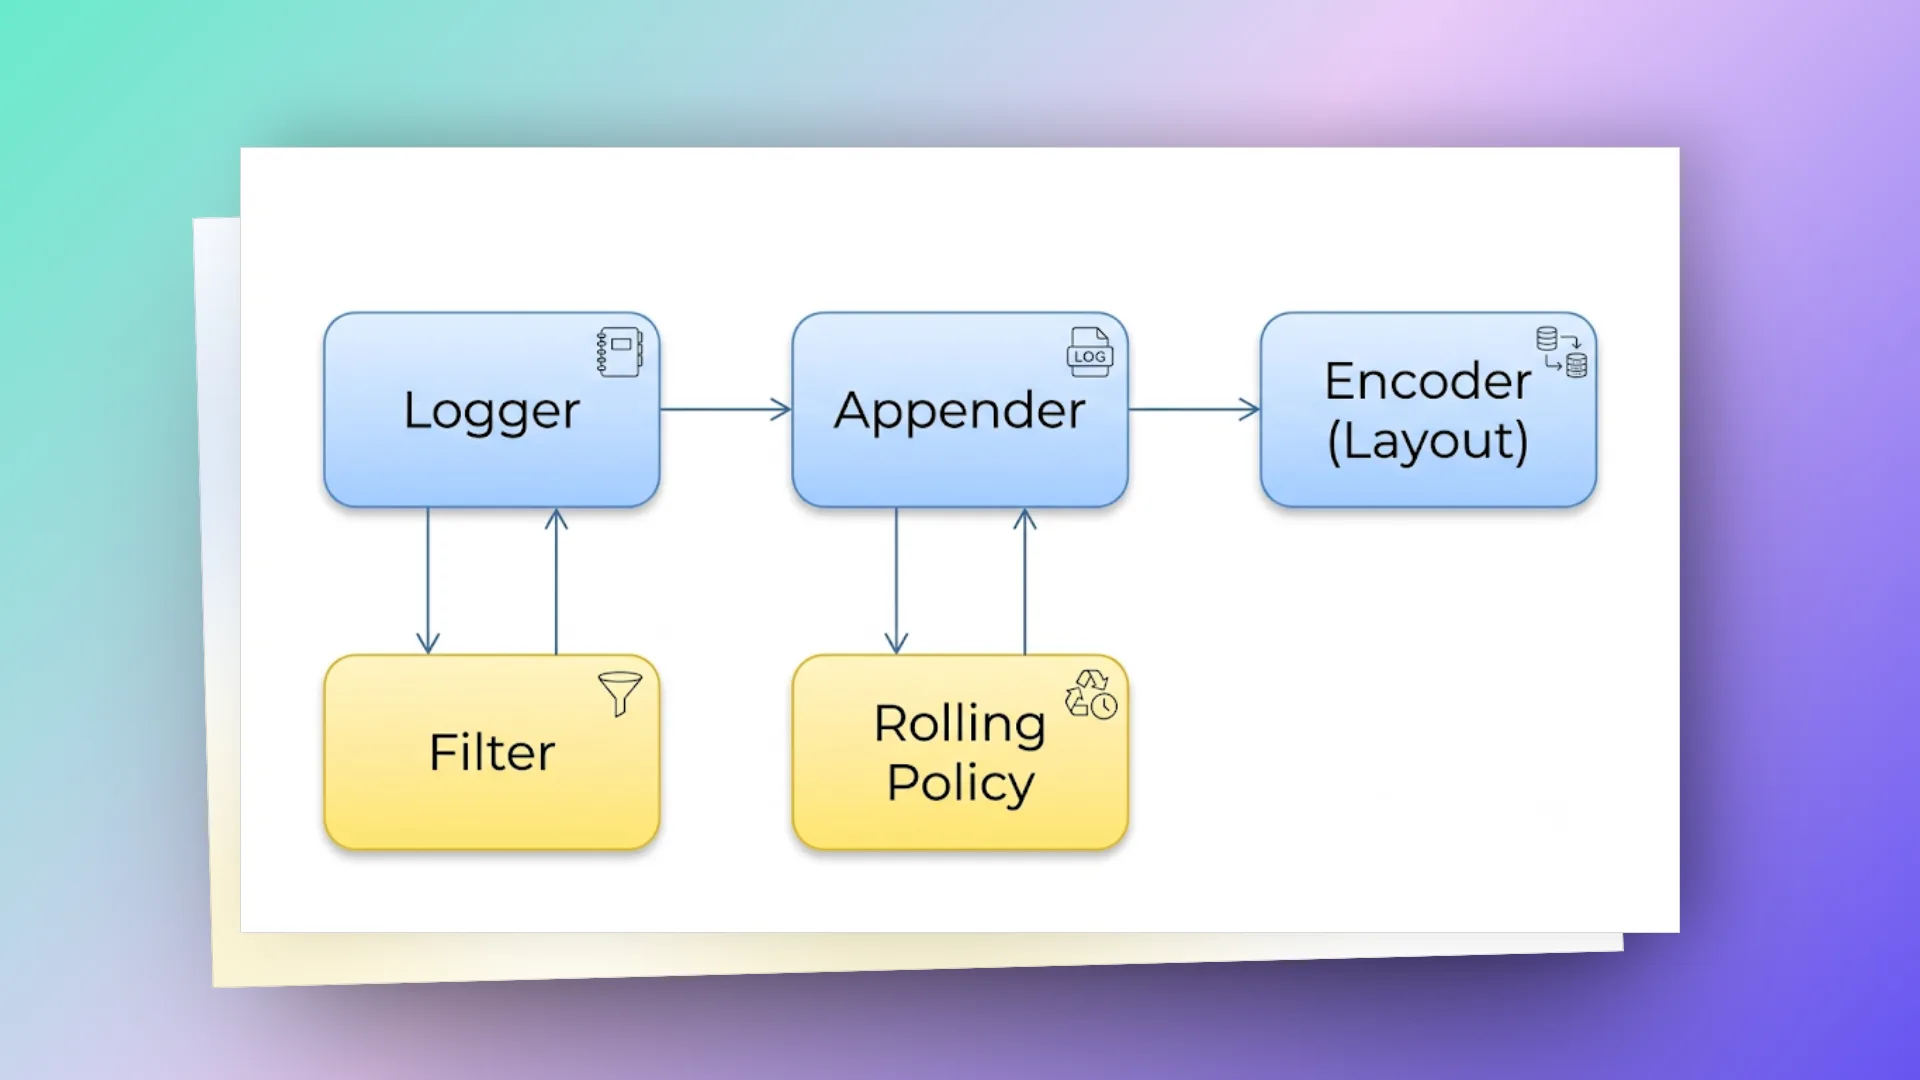
- Logger: a named entity that captures log events (e.g.
com.myapp.service.OrderService) - Appender: where log events go (console, file, network)
- Encoder/Layout: turns a log event into a string or byte array
- Filter: decides whether a log event gets processed
- Rolling Policy: handles log file rotation
# a production-ready logback-spring.xml
Most tutorials stop at a 5-line Logback config. A real production config looks more like this:
<?xml version="1.0" encoding="UTF-8"?>
<configuration>

   <!-- Properties -->
   <springProperty scope="context" name="APP_NAME" source="spring.application.name"
                   defaultValue="unknown-service"/>
   <springProperty scope="context" name="APP_ENV" source="spring.profiles.active"
                   defaultValue="local"/>

   <property name="LOG_PATH" value="${LOG_PATH:-./logs}"/>
   <property name="LOG_PATTERN"
             value="%d{yyyy-MM-dd HH:mm:ss.SSS} [%thread] [%X{traceId:-}] [%X{spanId:-}] [%X{requestId:-}] %-5level %logger{36} - %msg%n"/>
   <property name="JSON_LOG_PATTERN"
             value='{"timestamp":"%d{yyyy-MM-dd HH:mm:ss.SSS}","level":"%level","thread":"%thread","traceId":"%X{traceId:-}","spanId":"%X{spanId:-}","requestId":"%X{requestId:-}","logger":"%logger{36}","message":"%msg","service":"${APP_NAME}","env":"${APP_ENV}"}%n'/>

   <!-- Console Appender - Human readable for local dev -->
   <springProfile name="local,dev">
       <appender name="CONSOLE" class="ch.qos.logback.core.ConsoleAppender">
           <encoder>
               <pattern>${LOG_PATTERN}</pattern>
           </encoder>
       </appender>
   </springProfile>

   <!-- Console Appender - JSON for production (structured logging) -->
   <springProfile name="staging,production">
       <appender name="CONSOLE" class="ch.qos.logback.core.ConsoleAppender">
           <encoder>
               <pattern>${JSON_LOG_PATTERN}</pattern>
           </encoder>
       </appender>
   </springProfile>

   <!-- File Appender with Rolling -->
   <appender name="FILE" class="ch.qos.logback.core.rolling.RollingFileAppender">
       <file>${LOG_PATH}/${APP_NAME}.log</file>
       <rollingPolicy class="ch.qos.logback.core.rolling.SizeAndTimeBasedRollingPolicy">
           <fileNamePattern>${LOG_PATH}/${APP_NAME}.%d{yyyy-MM-dd}.%i.log.gz</fileNamePattern>
           <maxFileSize>100MB</maxFileSize>
           <maxHistory>30</maxHistory>
           <totalSizeCap>3GB</totalSizeCap>
       </rollingPolicy>
       <encoder>
           <pattern>${LOG_PATTERN}</pattern>
       </encoder>
   </appender>

   <!-- Async wrapper for FILE appender -->
   <appender name="ASYNC_FILE" class="ch.qos.logback.classic.AsyncAppender">
       <queueSize>512</queueSize>
       <discardingThreshold>0</discardingThreshold>
       <includeCallerData>false</includeCallerData>
       <appender-ref ref="FILE"/>
   </appender>

   <!-- Root Logger -->
   <root level="INFO">
       <appender-ref ref="CONSOLE"/>
       <appender-ref ref="ASYNC_FILE"/>
   </root>

   <!-- Application-specific logging -->
   <logger name="com.myapp" level="DEBUG" additivity="false">
       <appender-ref ref="CONSOLE"/>
       <appender-ref ref="ASYNC_FILE"/>
   </logger>

   <!-- Reduce noise from frameworks -->
   <logger name="org.springframework" level="WARN"/>
   <logger name="org.hibernate" level="WARN"/>
   <logger name="org.apache.kafka" level="WARN"/>
   <logger name="io.netty" level="WARN"/>

</configuration>
Things worth noticing:
%X{traceId:-}: this is MDC at work. More on it below- Profile-based config: JSON in production, readable text locally. Note that
CONSOLEonly exists when one of those four profiles is active; start the app with no profile and the root logger points at an appender that was never defined, so Logback just warns and console output disappears. Adddefaultto the local block (<springProfile name="local,dev,default">; Spring treatsdefaultas active when no other profile is) so there's always a console appender - AsyncAppender: matters a lot for performance, since logging shouldn't block business logic
discardingThreshold=0: never drop logs, even under load (tune this to your needs). The flip side: when the queue is full, the logging thread blocks until there's room- No
scan="true": Logback's config scanning doesn't work with Spring extensions like<springProfile>and<springProperty>; Spring Boot's docs say a rescan just logs "no applicable action" errors. To change log levels at runtime, use the Actuator/actuator/loggersendpoint instead
One caveat about JSON_LOG_PATTERN: it builds JSON by string concatenation, and %msg isn't escaped. A message containing a double quote (User said "hi") or a multi-line stack trace produces invalid JSON. It's fine as a starting point, but for real structured logs use an encoder that escapes properly: the Logstash encoder (covered below) or, from Spring Boot 3.4, the built-in logging.structured.format.console=ecs|logstash|gelf.
# mdc deep dive
# what is mdc?
MDC is basically a thread-local Map<String, String> that the logging framework manages for you. Whatever key-value pair you put into it shows up in your log pattern through %X{key}.
Think of it as hidden metadata attached to every log statement on the current thread, without you passing it around as a parameter.
# the mdc api
import org.slf4j.MDC;

// Put a value
MDC.put("requestId", "abc-123");

// Get a value
String requestId = MDC.get("requestId");

// Remove a value
MDC.remove("requestId");

// Clear all values
MDC.clear();

// Get a copy of the entire context map
Map<String, String> contextMap = MDC.getCopyOfContextMap();

// Set the entire context map (useful for propagation)
MDC.setContextMap(contextMap);
# How mdc works under the hood
Logback's MDC implementation uses ThreadLocal<Map<String, String>>:
Thread-1: MDC Map = {"requestId": "abc-123", "userId": "user-456"}
Thread-2: MDC Map = {"requestId": "def-789", "userId": "user-012"}
Thread-3: MDC Map = {} (empty)
When Logback handles a log event, it takes a snapshot of the current thread's MDC map. %X{key} in your layout reads from that snapshot.
That's both MDC's biggest strength and its weak spot:
- Strength: context follows you around inside a thread for free
- Weak spot: context is gone as soon as work moves to another thread (thread pools, async calls, reactive streams)
# mdc lifecycle: the #1 mistake
The most common MDC bug is simply forgetting to clean up:
// ❌ BAD: MDC leak
public void processOrder(Order order) {
   MDC.put("orderId", order.getId());
   orderService.process(order); // What if this throws?
   MDC.remove("orderId"); // Never reached on exception!
}

// ✅ GOOD: Always clean up with try-finally
public void processOrder(Order order) {
   MDC.put("orderId", order.getId());
   try {
       orderService.process(order);
   } finally {
       MDC.remove("orderId");
   }
}

// ✅ BETTER: Use MDC.putCloseable (SLF4J 1.7+)
public void processOrder(Order order) {
   try (MDC.MDCCloseable ignored = MDC.putCloseable("orderId", order.getId())) {
       orderService.process(order);
   }
}
Servlet containers reuse threads from a pool, so a value leaked by Request A ends up in the logs of Request B. Debugging that is a special kind of confusing.
# mdc with thread pools: the propagation problem
This is where most teams get bitten:
// ❌ MDC context is LOST when task runs on executor thread
ExecutorService executor = Executors.newFixedThreadPool(10);

MDC.put("requestId", "abc-123");
executor.submit(() -> {
   // MDC.get("requestId") returns null here!
   log.info("Processing async task"); // No requestId in logs
});
The fix is to wrap your tasks so they carry MDC along:
public class MdcAwareRunnable implements Runnable {
   private final Runnable delegate;
   private final Map<String, String> contextMap;

   public MdcAwareRunnable(Runnable delegate) {
       this.delegate = delegate;
       this.contextMap = MDC.getCopyOfContextMap(); // Capture at submission time
   }

   @Override
   public void run() {
       Map<String, String> previousContext = MDC.getCopyOfContextMap();
       try {
           if (contextMap != null) {
               MDC.setContextMap(contextMap);
           }
           delegate.run();
       } finally {
           if (previousContext != null) {
               MDC.setContextMap(previousContext);
           } else {
               MDC.clear();
           }
       }
   }
}

// Usage
executor.submit(new MdcAwareRunnable(() -> {
   log.info("Processing async task"); // requestId is now available!
}));
Even better, make the executor itself MDC-aware:
public class MdcAwareExecutorService implements ExecutorService {
   private final ExecutorService delegate;

   public MdcAwareExecutorService(ExecutorService delegate) {
       this.delegate = delegate;
   }

   @Override
   public <T> Future<T> submit(Callable<T> task) {
       Map<String, String> contextMap = MDC.getCopyOfContextMap();
       return delegate.submit(() -> {
           Map<String, String> previous = MDC.getCopyOfContextMap();
           try {
               if (contextMap != null) MDC.setContextMap(contextMap);
               return task.call();
           } finally {
               if (previous != null) MDC.setContextMap(previous);
               else MDC.clear();
           }
       });
   }

   @Override
   public Future<?> submit(Runnable task) {
       return submit(Executors.callable(task, null));
   }

   // ... delegate other methods similarly
}
# spring's taskDecorator: the clean way
For @Async methods, Spring gives you a tidier option:
@Configuration
@EnableAsync
public class AsyncConfig implements AsyncConfigurer {

   @Override
   public Executor getAsyncExecutor() {
       ThreadPoolTaskExecutor executor = new ThreadPoolTaskExecutor();
       executor.setCorePoolSize(10);
       executor.setMaxPoolSize(50);
       executor.setQueueCapacity(100);
       executor.setThreadNamePrefix("async-");
       executor.setTaskDecorator(new MdcTaskDecorator()); // Key line!
       executor.initialize();
       return executor;
   }
}

public class MdcTaskDecorator implements TaskDecorator {
   @Override
   public Runnable decorate(Runnable runnable) {
       Map<String, String> contextMap = MDC.getCopyOfContextMap();
       return () -> {
           try {
               if (contextMap != null) {
                   MDC.setContextMap(contextMap);
               }
               runnable.run();
           } finally {
               MDC.clear();
           }
       };
   }
}
Now every @Async method picks up the MDC context of the calling thread automatically.
Two notes. The finally { MDC.clear(); } assumes the task runs on a pool thread. If you set CallerRunsPolicy as the rejection policy, a rejected task runs on the caller's own thread, and that clear() wipes the caller's MDC; restoring the previous map (like MdcAwareRunnable above) is the safer version. And if you're on Spring Framework 6.1+ (Spring Boot 3.2+) with Micrometer's context-propagation library, there's a ready-made ContextPropagatingTaskDecorator that carries MDC and the tracing context over for you.
# building a correlation id system from scratch
Before reaching for a full tracing framework, it's worth building a simple correlation ID system by hand. Why bother:
- You learn how the pieces actually work
- Sometimes a full tracing framework is more than you need
- It's a good base to build on later
# the filter: entry point for every request
@Component
@Order(Ordered.HIGHEST_PRECEDENCE)
public class CorrelationIdFilter extends OncePerRequestFilter {

   private static final String CORRELATION_ID_HEADER = "X-Correlation-ID";
   private static final String REQUEST_ID_KEY = "requestId";
   private static final String CLIENT_IP_KEY = "clientIp";
   private static final String REQUEST_URI_KEY = "requestUri";
   private static final String REQUEST_METHOD_KEY = "requestMethod";

   @Override
   protected void doFilterInternal(HttpServletRequest request,
                                    HttpServletResponse response,
                                    FilterChain filterChain) throws ServletException, IOException {

       try {
           // Extract or generate correlation ID
           String correlationId = extractOrGenerateCorrelationId(request);

           // Populate MDC
           MDC.put(REQUEST_ID_KEY, correlationId);
           MDC.put(CLIENT_IP_KEY, getClientIp(request));
           MDC.put(REQUEST_URI_KEY, request.getRequestURI());
           MDC.put(REQUEST_METHOD_KEY, request.getMethod());

           // Add correlation ID to response header (for client-side correlation)
           response.addHeader(CORRELATION_ID_HEADER, correlationId);

           // Continue the filter chain
           filterChain.doFilter(request, response);

       } finally {
           // CRITICAL: Always clean up MDC
           MDC.clear();
       }
   }

   private String extractOrGenerateCorrelationId(HttpServletRequest request) {
       String correlationId = request.getHeader(CORRELATION_ID_HEADER);
       if (correlationId == null || correlationId.isBlank()) {
           correlationId = generateCorrelationId();
       }
       return correlationId;
   }

   private String generateCorrelationId() {
       // Use a compact, URL-safe format
       // Prefix with timestamp for rough chronological ordering
       return String.format("%s-%s",
               Long.toHexString(System.currentTimeMillis()),
               UUID.randomUUID().toString().substring(0, 8));
   }

   private String getClientIp(HttpServletRequest request) {
       String xForwardedFor = request.getHeader("X-Forwarded-For");
       if (xForwardedFor != null && !xForwardedFor.isBlank()) {
           return xForwardedFor.split(",")[0].trim();
       }
       return request.getRemoteAddr();
   }
}
Two things to tighten before this goes to production. The incoming X-Correlation-ID comes from the client, so validate it (length, allowed characters) before putting it into MDC, otherwise anyone can inject newlines or fake fields into your logs. And X-Forwarded-For is just as easy to forge: only trust it when the request came through your own proxy or load balancer. Spring Boot's server.forward-headers-strategy handles that more carefully than splitting the header by hand.
# propagating correlation id to downstream services
When Service A calls Service B, the correlation ID has to go along with the request:
@Component
public class CorrelationIdRestTemplateInterceptor implements ClientHttpRequestInterceptor {

   private static final String CORRELATION_ID_HEADER = "X-Correlation-ID";

   @Override
   public ClientHttpResponse intercept(HttpRequest request, byte[] body,
                                        ClientHttpRequestExecution execution) throws IOException {
       String correlationId = MDC.get("requestId");
       if (correlationId != null) {
           request.getHeaders().add(CORRELATION_ID_HEADER, correlationId);
       }
       return execution.execute(request, body);
   }
}

@Configuration
public class RestTemplateConfig {

   @Bean
   public RestTemplate restTemplate(CorrelationIdRestTemplateInterceptor interceptor) {
       RestTemplate restTemplate = new RestTemplate();
       restTemplate.setInterceptors(List.of(interceptor));
       return restTemplate;
   }
}
For WebClient:
@Configuration
public class WebClientConfig {

   @Bean
   public WebClient webClient() {
       return WebClient.builder()
               .filter((request, next) -> {
                   String correlationId = MDC.get("requestId");
                   if (correlationId != null) {
                       return next.exchange(
                           ClientRequest.from(request)
                               .header("X-Correlation-ID", correlationId)
                               .build()
                       );
                   }
                   return next.exchange(request);
               })
               .build();
   }
}
Both examples build the client by hand (new RestTemplate(), WebClient.builder()), which is fine for a home-grown correlation ID. Keep in mind for the tracing section later: Micrometer only instruments clients built from the auto-configured RestTemplateBuilder, RestClient.Builder or WebClient.Builder beans. A client created by hand won't propagate traceparent.
# propagating through message queues
For Kafka:
// Producer side: inject correlation ID into message headers.
// Kafka instantiates interceptors itself from the "interceptor.classes" producer property
// (e.g. spring.kafka.producer.properties.interceptor.classes), so @Component alone does nothing.
public class CorrelationIdKafkaProducerInterceptor implements ProducerInterceptor<String, String> {

   @Override
   public ProducerRecord<String, String> onSend(ProducerRecord<String, String> record) {
       String correlationId = MDC.get("requestId");
       if (correlationId != null) {
           record.headers().add("X-Correlation-ID", correlationId.getBytes(StandardCharsets.UTF_8));
       }
       return record;
   }

   // ... other methods
}

// Consumer side: extract correlation ID from message headers
@KafkaListener(topics = "orders")
public void handleOrder(ConsumerRecord<String, String> record) {
   Header correlationHeader = record.headers().lastHeader("X-Correlation-ID");
   String correlationId = correlationHeader != null
           ? new String(correlationHeader.value(), StandardCharsets.UTF_8)
           : UUID.randomUUID().toString();

   MDC.put("requestId", correlationId);
   try {
       // Process the message
       processOrder(record.value());
   } finally {
       MDC.clear();
   }
}
Once you move to Micrometer Tracing (next sections), Spring for Apache Kafka can carry the trace context through record headers for you: turn on observationEnabled on KafkaTemplate and on the listener container (in Spring Boot: spring.kafka.template.observation-enabled and spring.kafka.listener.observation-enabled).
# the result
With that in place, the logs look like this:
# Service A (API Gateway)
2024-03-15 10:30:01.123 [http-nio-8080-exec-1] [18f3a2b1-c4d5e6f7] INFO  OrderController - Received order request
2024-03-15 10:30:01.125 [http-nio-8080-exec-1] [18f3a2b1-c4d5e6f7] INFO  OrderController - Calling payment service

# Service B (Payment Service)
2024-03-15 10:30:01.130 [http-nio-8081-exec-3] [18f3a2b1-c4d5e6f7] INFO  PaymentController - Processing payment
2024-03-15 10:30:01.250 [http-nio-8081-exec-3] [18f3a2b1-c4d5e6f7] INFO  PaymentService - Payment successful

# Service C (Inventory Service, triggered via Kafka)
2024-03-15 10:30:01.300 [kafka-consumer-1] [18f3a2b1-c4d5e6f7] INFO  InventoryListener - Reserving stock
2024-03-15 10:30:01.450 [kafka-consumer-1] [18f3a2b1-c4d5e6f7] INFO  InventoryService - Stock reserved
Grep for 18f3a2b1-c4d5e6f7 across all services and you get the whole request flow. That alone is a huge step up.
We can still do better, though.
# spring boot integration patterns
# handlerInterceptor vs filter: when to use which
Both can set up MDC, but they're good at different things:
| Aspect | Filter (Servlet) | HandlerInterceptor (Spring MVC) |
|---|---|---|
| Scope | All requests (including static resources) | Only requests handled by DispatcherServlet |
| Access to | HttpServletRequest/Response | HandlerMethod, ModelAndView |
| MDC cleanup | In finally block | In afterCompletion() |
| Order control | @Order or FilterRegistrationBean | InterceptorRegistry.addInterceptor().order() |
| Recommendation | Use for correlation ID (runs first) | Use for business context (user ID, tenant ID) |
# adding business context with handlerInterceptor
@Component
public class BusinessContextInterceptor implements HandlerInterceptor {

   private final JwtTokenProvider tokenProvider;

   public BusinessContextInterceptor(JwtTokenProvider tokenProvider) {
       this.tokenProvider = tokenProvider;
   }

   @Override
   public boolean preHandle(HttpServletRequest request, HttpServletResponse response,
                             Object handler) {
       // Extract user context from JWT
       String authHeader = request.getHeader("Authorization");
       if (authHeader != null && authHeader.startsWith("Bearer ")) {
           try {
               String token = authHeader.substring(7);
               Claims claims = tokenProvider.parseToken(token);

               MDC.put("userId", claims.getSubject());
               MDC.put("tenantId", claims.get("tenantId", String.class));
               MDC.put("userRole", claims.get("role", String.class));
           } catch (Exception e) {
               // Don't fail the request just because we can't extract context
               // The security filter will handle authentication
           }
       }
       return true;
   }

   @Override
   public void afterCompletion(HttpServletRequest request, HttpServletResponse response,
                                Object handler, Exception ex) {
       MDC.remove("userId");
       MDC.remove("tenantId");
       MDC.remove("userRole");
   }
}

@Configuration
public class WebMvcConfig implements WebMvcConfigurer {

   @Autowired
   private BusinessContextInterceptor businessContextInterceptor;

   @Override
   public void addInterceptors(InterceptorRegistry registry) {
       registry.addInterceptor(businessContextInterceptor)
               .addPathPatterns("/api/**")
               .order(1);
   }
}
Now the logs carry business context too:
2024-03-15 10:30:01.123 [http-nio-8080-exec-1] [18f3a2b1-c4d5e6f7] [user-456] [tenant-acme] INFO OrderController - Received order request
# AOP-Based mdc for method-level context
Sometimes you want to add context per method:
@Target(ElementType.METHOD)
@Retention(RetentionPolicy.RUNTIME)
public @interface LogContext {
   String key();
   String valueExpression(); // SpEL expression
}

@Aspect
@Component
public class LogContextAspect {

   private final SpelExpressionParser parser = new SpelExpressionParser();

   @Around("@annotation(logContext)")
   public Object addLogContext(ProceedingJoinPoint joinPoint, LogContext logContext) throws Throwable {
       String value = evaluateExpression(logContext.valueExpression(), joinPoint);

       MDC.put(logContext.key(), value);
       try {
           return joinPoint.proceed();
       } finally {
           MDC.remove(logContext.key());
       }
   }

   private String evaluateExpression(String expression, ProceedingJoinPoint joinPoint) {
       StandardEvaluationContext context = new StandardEvaluationContext();
       Object[] args = joinPoint.getArgs();
       MethodSignature signature = (MethodSignature) joinPoint.getSignature();
       String[] paramNames = signature.getParameterNames();

       for (int i = 0; i < paramNames.length; i++) {
           context.setVariable(paramNames[i], args[i]);
       }

       return parser.parseExpression(expression).getValue(context, String.class);
   }
}

// Usage
@LogContext(key = "orderId", valueExpression = "#order.id")
public OrderResult processOrder(Order order) {
   log.info("Processing order"); // orderId automatically in MDC
   // ...
}
# distributed tracing with micrometer tracing
# the evolution: sleuth → micrometer tracing
If you've used Spring for a while, you know Spring Cloud Sleuth. From Spring Boot 3.x, Sleuth is replaced by Micrometer Tracing. Same concepts, but the implementation now lives in the Micrometer observability stack.
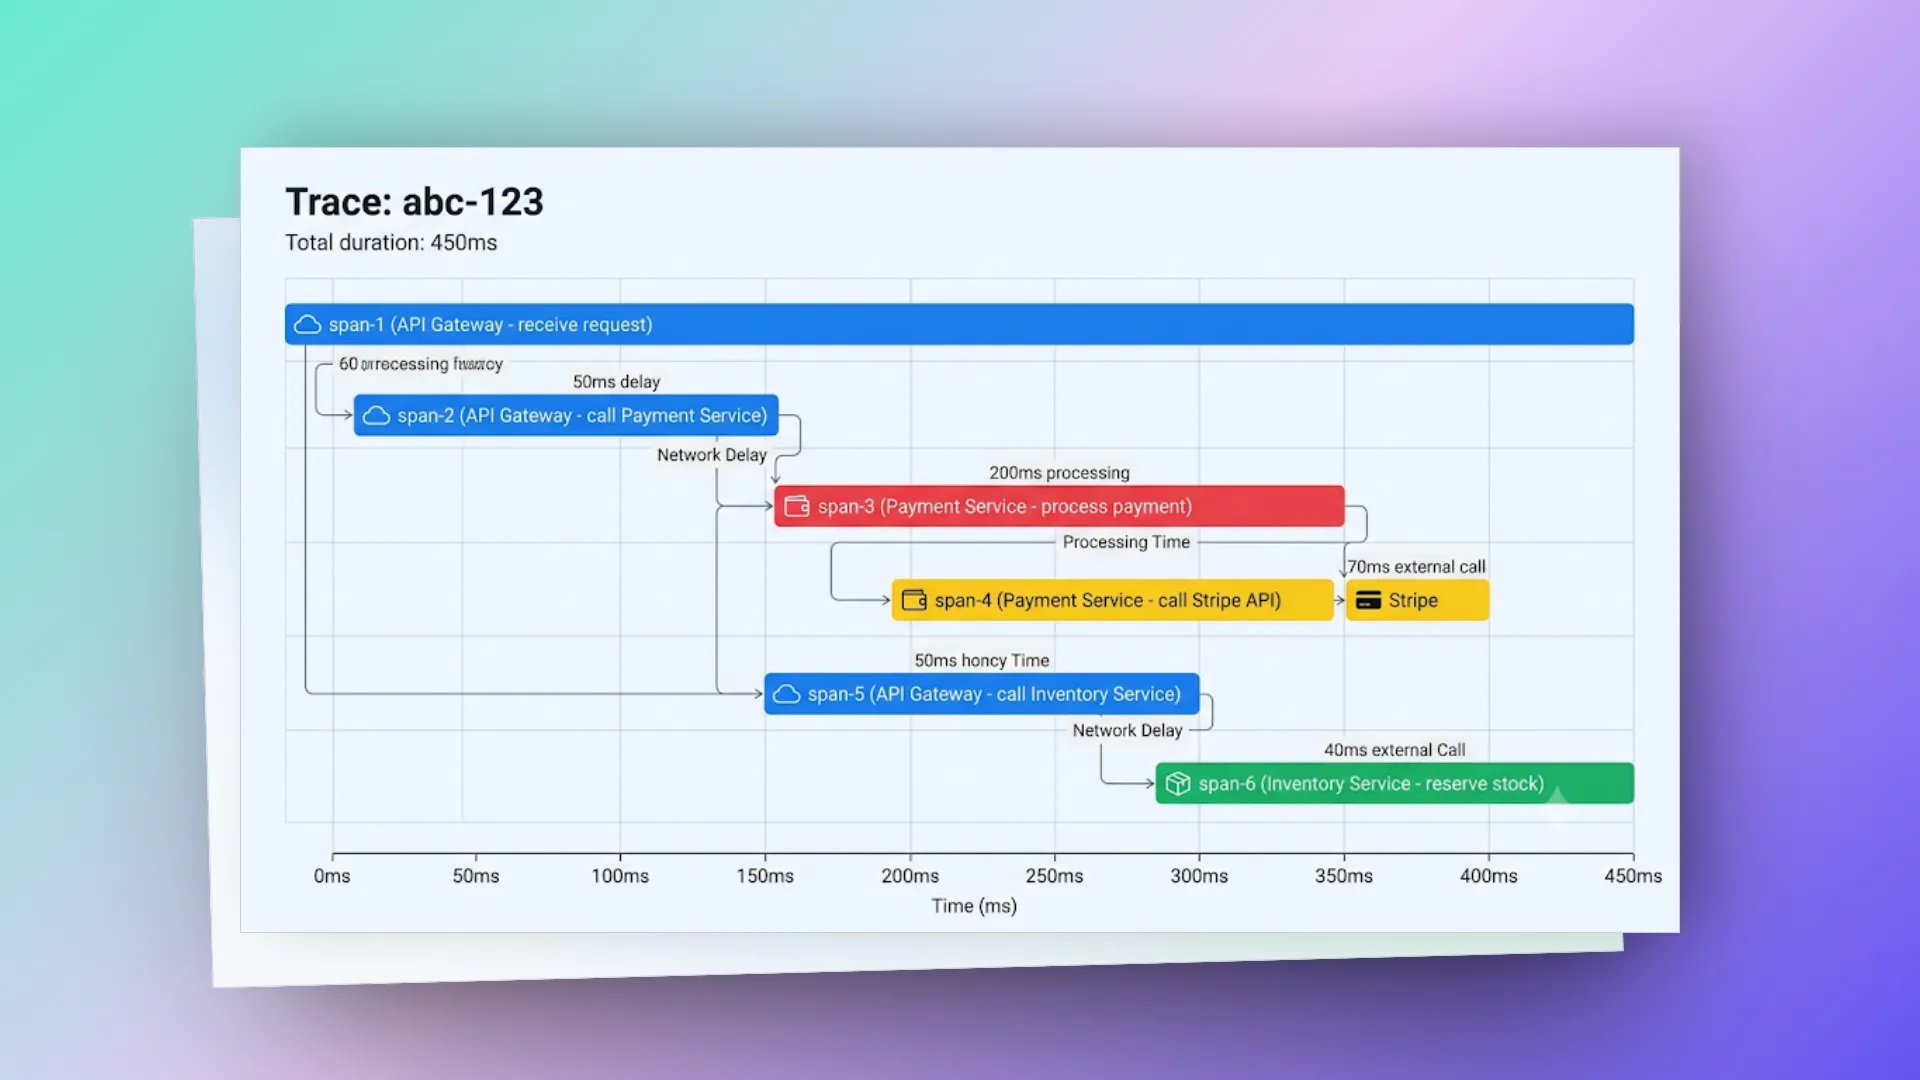
# key concepts
Some terms first, so we're on the same page:
- Trace: the whole path of a request across all services, identified by a
traceId. - Span: one unit of work inside a trace, identified by a
spanId. A trace is a tree of spans. - Parent Span: the span that started the current one. That's what gives you the cause-and-effect hierarchy.
- Baggage: key-value pairs that cross service boundaries (think MDC, but distributed).
- Sampling: deciding whether a trace gets recorded and exported (you don't need to keep every trace).
# setting up micrometer tracing with zipkin
# dependencies (maven)
<dependencies>
   <!-- Spring Boot Actuator (required for observability) -->
   <dependency>
       <groupId>org.springframework.boot</groupId>
       <artifactId>spring-boot-starter-actuator</artifactId>
   </dependency>

   <!-- Micrometer Tracing Bridge (choose ONE) -->
   <!-- Option A: Brave (Zipkin's tracing library) -->
   <dependency>
       <groupId>io.micrometer</groupId>
       <artifactId>micrometer-tracing-bridge-brave</artifactId>
   </dependency>

   <!-- Option B: OpenTelemetry -->
   <!--
   <dependency>
       <groupId>io.micrometer</groupId>
       <artifactId>micrometer-tracing-bridge-otel</artifactId>
   </dependency>
   -->

   <!-- Reporter: Send traces to Zipkin -->
   <dependency>
       <groupId>io.zipkin.reporter2</groupId>
       <artifactId>zipkin-reporter-brave</artifactId>
   </dependency>

   <!-- For WebClient integration -->
   <dependency>
       <groupId>org.springframework.boot</groupId>
       <artifactId>spring-boot-starter-webflux</artifactId>
   </dependency>
</dependencies>
# configuration
# application.yml
spring:
  application:
    name: order-service

management:
  tracing:
    sampling:
      probability: 1.0 # 100% sampling for dev; use 0.1 (10%) for production
  zipkin:
    tracing:
      endpoint: http://localhost:9411/api/v2/spans

logging:
  pattern:
    level: '%5p [${spring.application.name:},%X{traceId:-},%X{spanId:-}]'
That's all. With those dependencies and config, Spring Boot auto-configures:
- Trace and span ID generation
- MDC population with
traceIdandspanId - Propagation headers: W3C
traceparentby default; B3 (X-B3-TraceId...) only if you setmanagement.tracing.propagation.type=b3 - Auto-instrumentation for Spring MVC, plus RestTemplate, RestClient and WebClient built from the auto-configured builders (
RestTemplateBuilder,RestClient.Builder,WebClient.Builder) - Trace export to Zipkin
A few version notes. Spring Boot's default sampling probability is 0.1, so the 1.0 above is a deliberate dev setting. From Spring Boot 3.2, the default log pattern already includes [traceId-spanId] when tracing is on, so the logging.pattern.level override is only needed if you want a different format (3.2+ also has logging.pattern.correlation for exactly that). And this config uses Spring Boot 3.x property names: in Spring Boot 4 the Zipkin endpoint moved to management.tracing.export.zipkin.endpoint and there's a dedicated spring-boot-starter-zipkin, so check the docs for your version. One more: zipkin-reporter-brave only goes with the Brave bridge. If you pick option B (OpenTelemetry), the Zipkin exporter is io.opentelemetry:opentelemetry-exporter-zipkin instead.
# how it works behind the scenes
When a request arrives:
1. Request enters the servlet filter chain (before DispatcherServlet)
2. Spring's ServerHttpObservationFilter starts an Observation, which creates a new Span
3. If incoming headers contain trace context (traceparent/X-B3-*):
  → Extract traceId and create a child span
4. If no trace context:
  → Generate new traceId and root span
5. traceId and spanId are automatically put into MDC
6. Your log pattern picks them up via %X{traceId} and %X{spanId}
7. When you call another service via RestTemplate/WebClient:
  → Micrometer injects trace context into outgoing headers
8. When the span completes:
  → Span data is sent to Zipkin (async, non-blocking)
# custom spans for business operations
Auto-instrumentation covers HTTP calls, but you'll often want spans around business logic too:
@Service
public class OrderService {

   private static final Logger log = LoggerFactory.getLogger(OrderService.class);
   private final ObservationRegistry observationRegistry;

   public OrderService(ObservationRegistry observationRegistry) {
       this.observationRegistry = observationRegistry;
   }

   public OrderResult createOrder(CreateOrderRequest request) {
       return Observation.createNotStarted("order.create", observationRegistry)
               .lowCardinalityKeyValue("order.type", request.getType().name())
               .highCardinalityKeyValue("order.itemCount", String.valueOf(request.getItems().size()))
               .observe(() -> {
                   log.info("Creating order with {} items", request.getItems().size());

                   // Validate
                   validateOrder(request);

                   // Process payment
                   PaymentResult payment = processPayment(request);

                   // Reserve inventory
                   reserveInventory(request);

                   log.info("Order created successfully");
                   return new OrderResult(payment.getTransactionId());
               });
   }

   private void validateOrder(CreateOrderRequest request) {
       Observation.createNotStarted("order.validate", observationRegistry)
               .observe(() -> {
                   log.info("Validating order");
                   // validation logic
               });
   }
}
Or use @Observed to keep the code shorter:
@Configuration
public class ObservationConfig {
   @Bean
   public ObservedAspect observedAspect(ObservationRegistry registry) {
       return new ObservedAspect(registry);
   }
}

@Service
public class PaymentService {

   @Observed(name = "payment.process",
             contextualName = "process-payment",
             lowCardinalityKeyValues = {"payment.method", "credit_card"})
   public PaymentResult processPayment(PaymentRequest request) {
       // This entire method is now a span
       log.info("Processing payment of {}", request.getAmount());
       // ...
   }
}
The manual ObservedAspect bean is what Spring Boot 3.0/3.1 needed. From 3.2 on, you can drop it and set management.observations.annotations.enabled=true. Either way you need spring-boot-starter-aop on the classpath, and like any Spring AOP proxy, @Observed doesn't fire when a method calls another method on the same object.
# baggage: carrying business context across services
Baggage works like MDC, except it crosses service boundaries:
@Component
public class BaggageFilter extends OncePerRequestFilter {

   private final Tracer tracer;

   public BaggageFilter(Tracer tracer) {
       this.tracer = tracer;
   }

   @Override
   protected void doFilterInternal(HttpServletRequest request,
                                    HttpServletResponse response,
                                    FilterChain filterChain) throws ServletException, IOException {

       // Set baggage that will propagate to all downstream services
       try (BaggageInScope userId = tracer.createBaggageInScope("userId",
               extractUserId(request))) {
           try (BaggageInScope tenantId = tracer.createBaggageInScope("tenantId",
                   extractTenantId(request))) {
               filterChain.doFilter(request, response);
           }
       }
   }
}
Then configure which baggage fields get propagated:
management:
  tracing:
    baggage:
      remote-fields:
        - userId
        - tenantId
        - requestSource
      correlation:
        fields:
          - userId
          - tenantId
correlation.fields copies baggage values into MDC automatically, so they show up in your logs with no extra code.
Baggage goes out on every outgoing call, including calls to third-party APIs if they're instrumented too. Don't put anything in it you wouldn't send to an outside service.
# the reactive challenge: mdc in webFlux
# the problem
On Spring WebFlux (the reactive stack), MDC simply doesn't work out of the box. Here's why:
In reactive code, one request can hop across several threads. The Reactor scheduler may switch threads at any operator. MDC is thread-local, so your trace context just vanishes:
// In WebFlux, this LOSES MDC context
webClient.get().uri("/api/users")
   .retrieve()
   .bodyToMono(User.class)
   .map(user -> {
       log.info("Got user: {}", user.getName()); // MDC is empty here!
       return user;
   });
# solution 1: reactor context + hook (recommended for Spring Boot 3.x)
Spring Boot 3.x with Micrometer Tracing handles this for you through Reactor's Context Propagation library:
<dependency>
   <groupId>io.micrometer</groupId>
   <artifactId>context-propagation</artifactId>
</dependency>
// In your main application class or configuration
@PostConstruct
public void setupReactorContext() {
// This enables automatic context propagation in Reactor
Hooks.enableAutomaticContextPropagation();
}With that, Micrometer Tracing will:
- Store trace context in Reactor's
Context - Put it back into MDC when operators run
- Carry it through the whole reactive chain
On Spring Boot 3.2+ you don't need the @PostConstruct hook: set spring.reactor.context-propagation=auto and Boot calls Hooks.enableAutomaticContextPropagation() for you. If you do call it yourself, do it as early as possible (first line of main), before any reactive pipeline gets built.
# solution 2: manual context propagation (for custom mdc values)
If you need custom MDC values that Micrometer doesn't cover:
public class MdcContextLifter<T> implements CoreSubscriber<T> {

   private final CoreSubscriber<T> delegate;
   private final Map<String, String> mdcContext;

   public MdcContextLifter(CoreSubscriber<T> delegate) {
       this.delegate = delegate;
       this.mdcContext = delegate.currentContext()
               .getOrDefault("mdc", Collections.emptyMap());
   }

   @Override
   public void onSubscribe(Subscription s) {
       copyToMdc(mdcContext);
       delegate.onSubscribe(s);
   }

   @Override
   public void onNext(T t) {
       copyToMdc(mdcContext);
       delegate.onNext(t);
   }

   @Override
   public void onError(Throwable t) {
       copyToMdc(mdcContext);
       delegate.onError(t);
   }

   @Override
   public void onComplete() {
       copyToMdc(mdcContext);
       delegate.onComplete();
   }

   @Override
   public Context currentContext() {
       return delegate.currentContext();
   }

   private void copyToMdc(Map<String, String> context) {
       if (context != null && !context.isEmpty()) {
           MDC.setContextMap(context);
       } else {
           MDC.clear();
       }
   }
}
Register it as a Reactor hook:
@Configuration
public class ReactorMdcConfig {

   @PostConstruct
   public void setupMdcHook() {
       Hooks.onEachOperator("mdc",
           Operators.lift((scannable, subscriber) -> new MdcContextLifter<>(subscriber)));
   }

   @PreDestroy
   public void cleanupMdcHook() {
       Hooks.resetOnEachOperator("mdc");
   }
}
Usage in WebFlux:
@RestController
public class OrderController {

   @GetMapping("/orders/{id}")
   public Mono<Order> getOrder(@PathVariable String id) {
       return orderService.findById(id)
               .contextWrite(ctx -> ctx.put("mdc",
                   Map.of("orderId", id, "operation", "getOrder")));
   }
}
Be aware that Hooks.onEachOperator wraps every operator in every reactive chain in the application, so the cost grows with the length of your pipelines. With the context-propagation library from solution 1, the lighter option is usually to register a ThreadLocalAccessor for your own keys and let automatic propagation handle restoring them.
# solution 3: kotlin coroutines + mdc
If you use Kotlin coroutines with Spring WebFlux:
import kotlinx.coroutines.slf4j.MDCContext
import kotlinx.coroutines.withContext
import org.slf4j.MDC

@RestController
class OrderController(private val orderService: OrderService) {

   @GetMapping("/orders/{id}")
   suspend fun getOrder(@PathVariable id: String): Order {
       // Build the map first, then hand it to MDCContext
       val mdc = (MDC.getCopyOfContextMap() ?: emptyMap()) + ("orderId" to id)
       return withContext(MDCContext(mdc)) {
           orderService.findById(id)
       }
   }
}
The MDCContext element carries MDC across coroutine suspensions for you, but only the map it was created with. Calling MDC.put inside the coroutine doesn't stick: the kotlinx.coroutines docs say such updates are lost at the next suspension point. That's why the example builds the map first and passes it to MDCContext(...).
# advanced patterns for production
# pattern 1: structured logging with logstash encoder
Plain text logs are fine locally. In production you want structured (JSON) logs that ELK, Datadog, Splunk and friends can parse:
<dependency>
   <groupId>net.logstash.logback</groupId>
   <artifactId>logstash-logback-encoder</artifactId>
   <version>8.1</version> <!-- 8.x is built for Logback 1.5 (Spring Boot 3.3+); on Logback 1.3/1.4 stay on 7.4 -->
</dependency>
<!-- logback-spring.xml -->
<springProfile name="production">
<appender name="CONSOLE" class="ch.qos.logback.core.ConsoleAppender">
<encoder class="net.logstash.logback.encoder.LogstashEncoder">
<includeMdcKeyName>traceId</includeMdcKeyName>
<includeMdcKeyName>spanId</includeMdcKeyName>
<includeMdcKeyName>requestId</includeMdcKeyName>
<includeMdcKeyName>userId</includeMdcKeyName>
<includeMdcKeyName>tenantId</includeMdcKeyName>
<customFields>
{"service":"${APP_NAME}","env":"${APP_ENV}"}
</customFields>
<!-- StructuredArguments such as kv("orderId", id) are included by LogstashEncoder
out of the box, no extra provider needed -->
</encoder>
</appender>
</springProfile>Output:
{
  "@timestamp": "2024-03-15T10:30:01.123Z",
  "@version": "1",
  "message": "Order created successfully",
  "logger_name": "com.myapp.OrderController",
  "thread_name": "http-nio-8080-exec-1",
  "level": "INFO",
  "level_value": 20000,
  "traceId": "64f8a2b1c4d5e6f7a8b9c0d1e2f3a4b5",
  "spanId": "a8b9c0d1e2f3a4b5",
  "requestId": "18f3a2b1-c4d5e6f7",
  "userId": "user-456",
  "tenantId": "tenant-acme",
  "service": "order-service",
  "env": "production"
}
# pattern 2: dynamic log level with mdc
Turn up log levels for specific users or requests without redeploying:
// Custom Logback TurboFilter
public class MdcBasedTurboFilter extends TurboFilter {

   private final Set<String> debugUsers = ConcurrentHashMap.newKeySet();
   private final Set<String> debugTraces = ConcurrentHashMap.newKeySet();

   @Override
   public FilterReply decide(Marker marker, Logger logger, Level level,
                              String format, Object[] params, Throwable t) {

       String userId = MDC.get("userId");
       String traceId = MDC.get("traceId");

       // Enable DEBUG for specific users
       if (userId != null && debugUsers.contains(userId)) {
           return level.isGreaterOrEqual(Level.DEBUG)
                   ? FilterReply.ACCEPT : FilterReply.NEUTRAL;
       }

       // Enable DEBUG for specific traces
       if (traceId != null && debugTraces.contains(traceId)) {
           return level.isGreaterOrEqual(Level.DEBUG)
                   ? FilterReply.ACCEPT : FilterReply.NEUTRAL;
       }

       return FilterReply.NEUTRAL;
   }

   public void enableDebugForUser(String userId) {
       debugUsers.add(userId);
   }

   public void disableDebugForUser(String userId) {
       debugUsers.remove(userId);
   }
}
Expose it through an admin endpoint:
@RestController
@RequestMapping("/admin/logging")
public class DynamicLoggingController {

   private final MdcBasedTurboFilter turboFilter;

   @PostMapping("/debug/user/{userId}")
   public ResponseEntity<String> enableDebugForUser(@PathVariable String userId) {
       turboFilter.enableDebugForUser(userId);
       return ResponseEntity.ok("Debug enabled for user: " + userId);
   }

   @DeleteMapping("/debug/user/{userId}")
   public ResponseEntity<String> disableDebugForUser(@PathVariable String userId) {
       turboFilter.disableDebugForUser(userId);
       return ResponseEntity.ok("Debug disabled for user: " + userId);
   }
}
The snippet leaves out two pieces of glue. The filter has to be registered with Logback (((LoggerContext) LoggerFactory.getILoggerFactory()).addTurboFilter(filter)), and the controller needs the same instance, so the usual setup is a Spring bean that registers itself with the LoggerContext at startup (plus a constructor for the controller). And an endpoint that flips debug logging on in production must sit behind admin authentication, since DEBUG logs often contain data you don't want just anyone to switch on.
# pattern 3: request/response logging with mdc
@Component
@Order(Ordered.HIGHEST_PRECEDENCE + 1)
public class RequestResponseLoggingFilter extends OncePerRequestFilter {

   private static final Logger log = LoggerFactory.getLogger(RequestResponseLoggingFilter.class);

   @Override
   protected void doFilterInternal(HttpServletRequest request,
                                    HttpServletResponse response,
                                    FilterChain filterChain) throws ServletException, IOException {

       long startTime = System.nanoTime();

       // No ContentCachingResponseWrapper needed: HttpServletResponse.getStatus()
       // already gives the status, and buffering every response body in memory
       // just to read it would break streaming/SSE and waste heap.
       try {
           MDC.put("httpMethod", request.getMethod());
           MDC.put("httpUri", request.getRequestURI());

           log.info("Incoming request: {} {}", request.getMethod(), request.getRequestURI());

           filterChain.doFilter(request, response);

       } finally {
           long duration = (System.nanoTime() - startTime) / 1_000_000;

           MDC.put("httpStatus", String.valueOf(response.getStatus()));
           MDC.put("responseTimeMs", String.valueOf(duration));

           log.info("Completed request: {} {} → {} ({}ms)",
                   request.getMethod(),
                   request.getRequestURI(),
                   response.getStatus(),
                   duration);

           MDC.remove("httpMethod");
           MDC.remove("httpUri");
           MDC.remove("httpStatus");
           MDC.remove("responseTimeMs");
       }
   }

   @Override
   protected boolean shouldNotFilter(HttpServletRequest request) {
       String path = request.getRequestURI();
       // Skip health checks and actuator endpoints
       return path.startsWith("/actuator") || path.equals("/health");
   }
}
One gotcha: if an exception escapes the filter chain, the container hasn't turned it into a 500 yet when finally runs, so this log line may still show 200. Handle exceptions in @ControllerAdvice (pattern 4) so the status is set before the filter unwinds.
# pattern 4: error tracking with mdc
Add full context to error logs so debugging goes faster:
@ControllerAdvice
public class GlobalExceptionHandler {

   private static final Logger log = LoggerFactory.getLogger(GlobalExceptionHandler.class);

   @ExceptionHandler(Exception.class)
   public ResponseEntity<ErrorResponse> handleException(Exception ex, HttpServletRequest request) {
       String errorId = UUID.randomUUID().toString().substring(0, 8);

       MDC.put("errorId", errorId);
       MDC.put("errorType", ex.getClass().getSimpleName());

       log.error("Unhandled exception [errorId={}]: {}", errorId, ex.getMessage(), ex);

       MDC.remove("errorId");
       MDC.remove("errorType");

       ErrorResponse errorResponse = new ErrorResponse(
               errorId,
               "An internal error occurred. Reference: " + errorId,
               request.getRequestURI()
       );

       return ResponseEntity.status(HttpStatus.INTERNAL_SERVER_ERROR).body(errorResponse);
   }
}
The user gets an error ID to send to support, and you can find the full stack trace with all its MDC context right away.
# performance considerations
# mdc overhead
MDC operations are fast but not free. The numbers below are rough orders of magnitude rather than an official benchmark; they vary with JVM, CPU and Logback version, so measure with JMH if it really matters to you:
| Operation | Approximate Cost |
|---|---|
MDC.put() | ~50-100ns |
MDC.get() | ~30-50ns |
MDC.getCopyOfContextMap() | ~200-500ns (depends on map size) |
MDC.clear() | ~50ns |
For most apps that's nothing. If you're handling millions of events per second, though, keep an eye on:
How often you copy the map:
getCopyOfContextMap()creates a new HashMap every call. In high-throughput async code that adds up to a lot of garbage.AsyncAppender tuning: the default queue size (256) can be too small for busy services:
<appender name="ASYNC" class="ch.qos.logback.classic.AsyncAppender">
   <queueSize>1024</queueSize>
   <discardingThreshold>20</discardingThreshold> <!-- Drop TRACE/DEBUG/INFO once fewer than 20 slots remain (default: queueSize/5) -->
   <includeCallerData>false</includeCallerData> <!-- Expensive! Only enable for debugging -->
   <neverBlock>true</neverBlock> <!-- Don't block application threads; when the queue is full, events (even ERROR) are dropped -->
   <appender-ref ref="FILE"/>
</appender>- Sampling in production: don't export 100% of traces in production:
management:
  tracing:
    sampling:
      probability: 0.1 # Sample 10% of traces
What about always keeping traces for critical paths or errors? A common snippet tags the current span with sampling.priority=1, but that's a Datadog/OpenTracing convention and does nothing in Brave or OpenTelemetry. With head-based sampling (what probability configures), the decision is made once when the root span starts and travels downstream in the traceparent header; tagging a span later can't change it. And at that moment nobody knows yet whether the request will fail.
If you need "keep all errors and slow or critical requests, sample the rest", the usual answer is tail-based sampling in the collector. Services export everything (probability: 1.0) to an OpenTelemetry Collector, which waits for the whole trace and then decides:
# OpenTelemetry Collector (contrib) config
processors:
  tail_sampling:
    decision_wait: 10s
    policies:
      - name: keep-errors
        type: status_code
        status_code:
          status_codes: [ERROR]
      - name: keep-payments
        type: string_attribute
        string_attribute:
          key: payment.critical
          values: ['true']
      - name: sample-the-rest
        type: probabilistic
        probabilistic:
          sampling_percentage: 10
The cost is that the network traffic from services to the collector stays at 100%; only storage and the backend get the savings.
# logback performance tips
- Use parameterized logging, always:
// ❌ String concatenation happens even if DEBUG is disabled
log.debug("Processing order " + orderId + " for user " + userId);

// ✅ Message only formatted if DEBUG is enabled (the arguments themselves are still evaluated)
log.debug("Processing order {} for user {}", orderId, userId);- Guard expensive log computations:
// ❌ toJson() is called even if TRACE is disabled
log.trace("Full request body: {}", request.toJson());

// ✅ Only compute if TRACE is enabled
if (log.isTraceEnabled()) {
   log.trace("Full request body: {}", request.toJson());
}- Use markers for filterable logging:
private static final Marker SECURITY = MarkerFactory.getMarker("SECURITY");
private static final Marker PERFORMANCE = MarkerFactory.getMarker("PERFORMANCE");

log.info(SECURITY, "Failed login attempt for user {}", username);
log.warn(PERFORMANCE, "Slow query detected: {}ms", queryTime);
<!-- Route SECURITY markers to a separate appender -->
<appender name="SECURITY_FILE" class="ch.qos.logback.core.rolling.RollingFileAppender">
<filter class="ch.qos.logback.core.filter.EvaluatorFilter">
<evaluator class="ch.qos.logback.classic.boolex.OnMarkerEvaluator">
<marker>SECURITY</marker>
</evaluator>
<onMatch>ACCEPT</onMatch>
<onMismatch>DENY</onMismatch>
</filter>
<!-- ... -->
</appender># putting it all together: a complete example
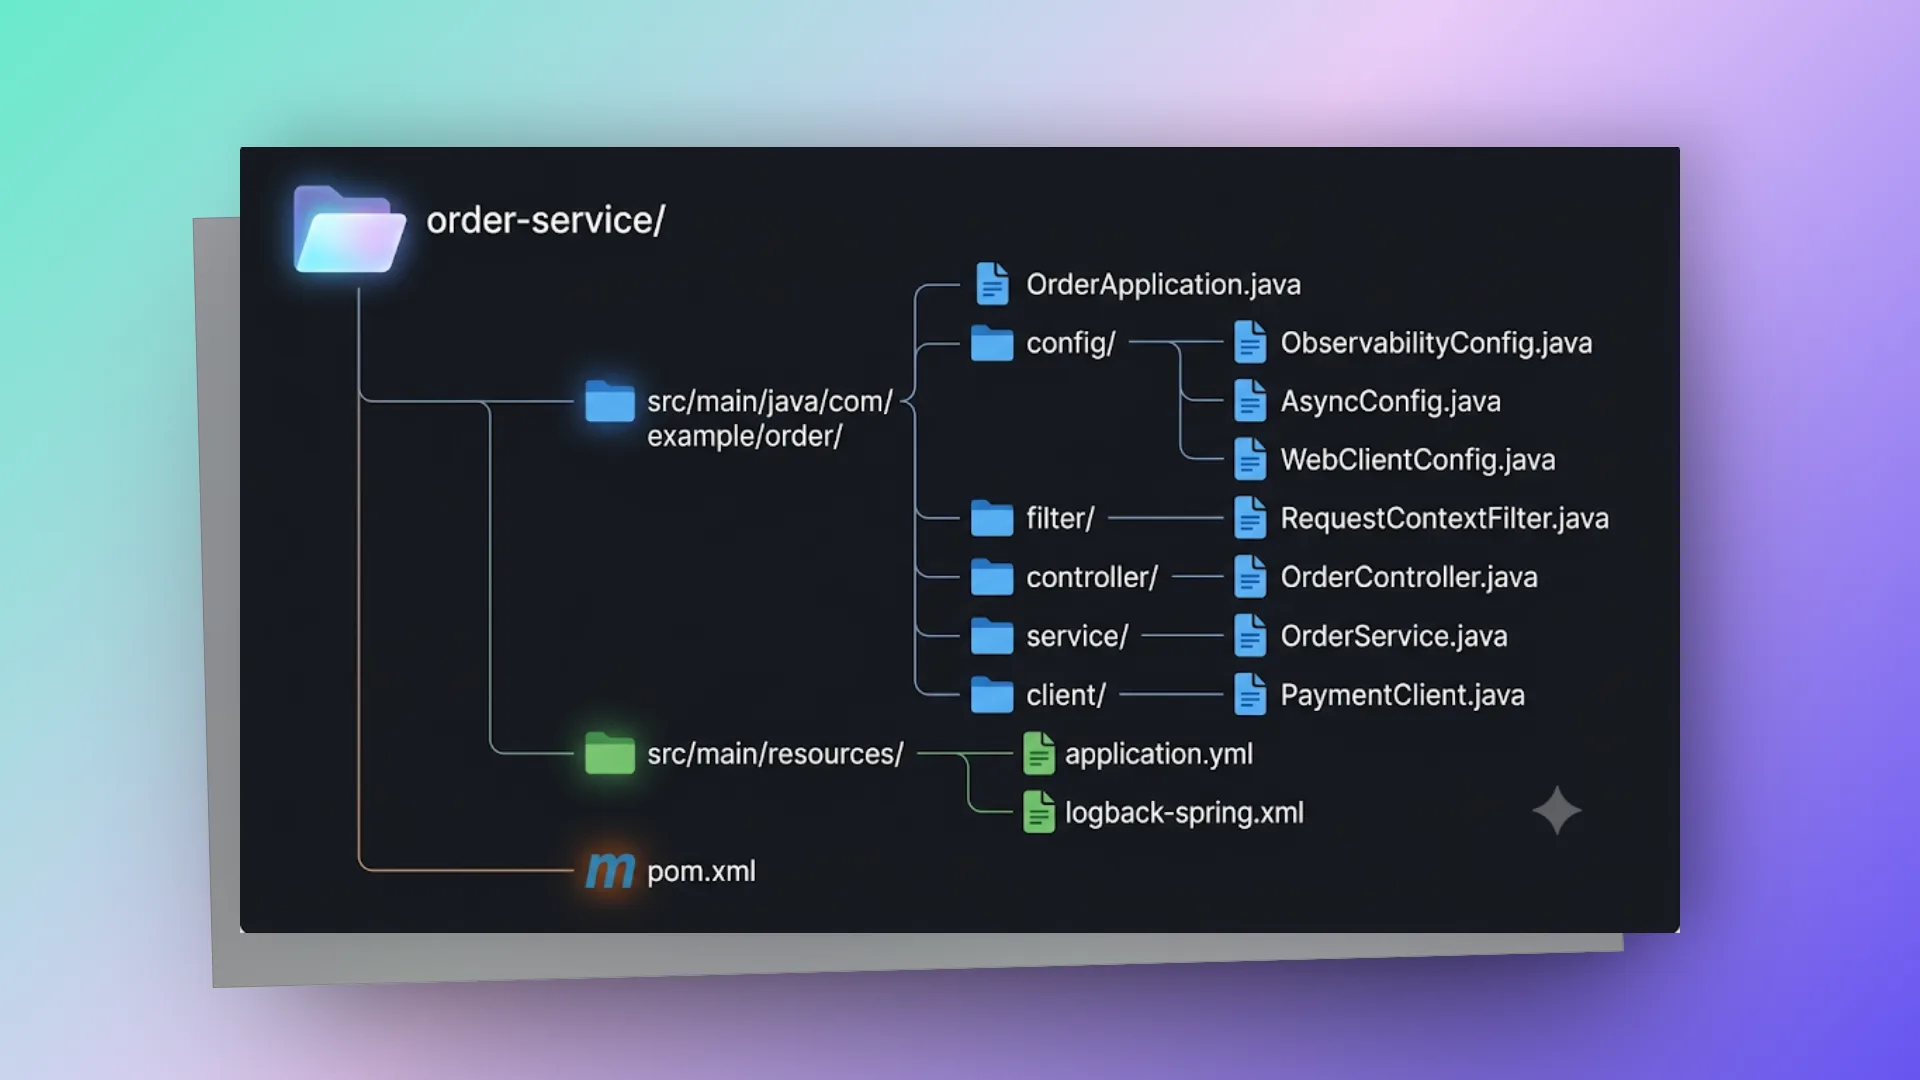
Here's a small but complete example that ties it all together: an order processing system with two services.
# project structure
# ObservabilityConfig.java
@Configuration
public class ObservabilityConfig {

   @Bean
   public ObservedAspect observedAspect(ObservationRegistry registry) {
       return new ObservedAspect(registry);
   }
}
# AsyncConfig.java
@Configuration
@EnableAsync
public class AsyncConfig implements AsyncConfigurer {

   @Override
   public Executor getAsyncExecutor() {
       return asyncExecutor();
   }

   // Exposed as a bean so it can be injected elsewhere (and in tests);
   // @Configuration proxying makes getAsyncExecutor() return this same instance
   @Bean
   public ThreadPoolTaskExecutor asyncExecutor() {
       ThreadPoolTaskExecutor executor = new ThreadPoolTaskExecutor();
       executor.setCorePoolSize(5);
       executor.setMaxPoolSize(20);
       executor.setQueueCapacity(50);
       executor.setThreadNamePrefix("async-");
       executor.setTaskDecorator(runnable -> {
           Map<String, String> contextMap = MDC.getCopyOfContextMap();
           return () -> {
               try {
                   if (contextMap != null) MDC.setContextMap(contextMap);
                   runnable.run();
               } finally {
                   MDC.clear();
               }
           };
       });
       return executor;
   }
}
# RequestContextFilter.java
@Component
// Run after Spring Boot's ServerHttpObservationFilter (HIGHEST_PRECEDENCE + 1),
// so traceId/spanId are already in MDC when we log
@Order(Ordered.HIGHEST_PRECEDENCE + 2)
public class RequestContextFilter extends OncePerRequestFilter {

   private static final Logger log = LoggerFactory.getLogger(RequestContextFilter.class);

   @Override
   protected void doFilterInternal(HttpServletRequest request,
                                    HttpServletResponse response,
                                    FilterChain filterChain) throws ServletException, IOException {
       long startTime = System.currentTimeMillis();

       try {
           MDC.put("clientIp", getClientIp(request));
           MDC.put("httpMethod", request.getMethod());
           MDC.put("httpUri", request.getRequestURI());

           log.info("→ {} {}", request.getMethod(), request.getRequestURI());
           filterChain.doFilter(request, response);

       } finally {
           long duration = System.currentTimeMillis() - startTime;
           log.info("← {} {} → {} ({}ms)",
                   request.getMethod(), request.getRequestURI(),
                   response.getStatus(), duration);
           // Remove only our own keys; traceId/spanId belong to the tracing scope
           MDC.remove("clientIp");
           MDC.remove("httpMethod");
           MDC.remove("httpUri");
       }
   }

   private String getClientIp(HttpServletRequest request) {
       String xff = request.getHeader("X-Forwarded-For");
       return (xff != null) ? xff.split(",")[0].trim() : request.getRemoteAddr();
   }

   @Override
   protected boolean shouldNotFilter(HttpServletRequest request) {
       return request.getRequestURI().startsWith("/actuator");
   }
}
# OrderController.java
@RestController
@RequestMapping("/api/orders")
public class OrderController {

   private static final Logger log = LoggerFactory.getLogger(OrderController.class);
   private final OrderService orderService;

   public OrderController(OrderService orderService) {
       this.orderService = orderService;
   }

   @PostMapping
   public ResponseEntity<OrderResponse> createOrder(@RequestBody CreateOrderRequest request) {
       log.info("Received order request with {} items", request.getItems().size());
       OrderResponse response = orderService.createOrder(request);
       log.info("Order {} created successfully", response.getOrderId());
       return ResponseEntity.status(HttpStatus.CREATED).body(response);
   }
}
# OrderService.java
@Service
public class OrderService {

   private static final Logger log = LoggerFactory.getLogger(OrderService.class);
   private final PaymentClient paymentClient;
   private final ObservationRegistry observationRegistry;

   public OrderService(PaymentClient paymentClient, ObservationRegistry observationRegistry) {
       this.paymentClient = paymentClient;
       this.observationRegistry = observationRegistry;
   }

   public OrderResponse createOrder(CreateOrderRequest request) {
       return Observation.createNotStarted("order.create", observationRegistry)
               .lowCardinalityKeyValue("order.type", request.getType())
               .observe(() -> {
                   String orderId = UUID.randomUUID().toString();
                   MDC.put("orderId", orderId);

                   try {
                       log.info("Validating order");
                       validateOrder(request);

                       log.info("Processing payment");
                       PaymentResponse payment = paymentClient.processPayment(
                               new PaymentRequest(orderId, request.getTotalAmount()));

                       log.info("Payment processed: txnId={}", payment.getTransactionId());

                       return new OrderResponse(orderId, "CONFIRMED", payment.getTransactionId());
                   } finally {
                       MDC.remove("orderId");
                   }
               });
   }

   private void validateOrder(CreateOrderRequest request) {
       Observation.createNotStarted("order.validate", observationRegistry)
               .observe(() -> {
                   if (request.getItems().isEmpty()) {
                       throw new IllegalArgumentException("Order must have at least one item");
                   }
                   log.info("Order validation passed");
               });
   }
}
# PaymentClient.java
@Component
public class PaymentClient {

   private static final Logger log = LoggerFactory.getLogger(PaymentClient.class);
   private final WebClient webClient;

   public PaymentClient(@Value("${services.payment.url}") String paymentUrl,
                         WebClient.Builder webClientBuilder) {
       this.webClient = webClientBuilder.baseUrl(paymentUrl).build();
   }

   public PaymentResponse processPayment(PaymentRequest request) {
       log.info("Calling payment service for order {}", request.getOrderId());

       return webClient.post()
               .uri("/api/payments")
               .bodyValue(request)
               .retrieve()
               .bodyToMono(PaymentResponse.class)
               .doOnSuccess(resp -> log.info("Payment service responded: {}", resp.getStatus()))
               .doOnError(err -> log.error("Payment service call failed: {}", err.getMessage()))
               .block();
   }
}
# application.yml
spring:
  application:
    name: order-service

server:
  port: 8080

services:
  payment:
    url: http://localhost:8081

management:
  tracing:
    sampling:
      probability: 1.0
  zipkin:
    tracing:
      endpoint: http://localhost:9411/api/v2/spans
  endpoints:
    web:
      exposure:
        include: health,info,metrics,prometheus

logging:
  level:
    com.example: DEBUG
    org.springframework.web: INFO
# logback-spring.xml
<?xml version="1.0" encoding="UTF-8"?>
<configuration>
   <springProperty scope="context" name="APP_NAME" source="spring.application.name"
                   defaultValue="app"/>

   <property name="CONSOLE_PATTERN"
             value="%d{HH:mm:ss.SSS} %highlight(%-5level) [%thread] [%X{traceId:-}|%X{spanId:-}] %cyan(%logger{24}) - %msg%n"/>

   <springProfile name="!production">
       <appender name="CONSOLE" class="ch.qos.logback.core.ConsoleAppender">
           <encoder>
               <pattern>${CONSOLE_PATTERN}</pattern>
           </encoder>
       </appender>
   </springProfile>

   <springProfile name="production">
       <appender name="CONSOLE" class="ch.qos.logback.core.ConsoleAppender">
           <encoder class="net.logstash.logback.encoder.LogstashEncoder">
               <customFields>{"service":"${APP_NAME}"}</customFields>
           </encoder>
       </appender>
   </springProfile>

   <root level="INFO">
       <appender-ref ref="CONSOLE"/>
   </root>

   <logger name="com.example" level="DEBUG"/>
</configuration>
# what the logs look like
Local development:
10:30:01.123 INFO  [http-nio-8080-exec-1] [64f8a2b1c4d5e6f7a8b9c0d1e2f3a4b5|a8b9c0d1e2f3a4b5] RequestContextFilter - → POST /api/orders
10:30:01.125 INFO  [http-nio-8080-exec-1] [64f8a2b1c4d5e6f7a8b9c0d1e2f3a4b5|a8b9c0d1e2f3a4b5] OrderController      - Received order request with 3 items
10:30:01.126 INFO  [http-nio-8080-exec-1] [64f8a2b1c4d5e6f7a8b9c0d1e2f3a4b5|b1c2d3e4f5a6b7c8] OrderService         - Validating order
10:30:01.127 INFO  [http-nio-8080-exec-1] [64f8a2b1c4d5e6f7a8b9c0d1e2f3a4b5|d4e5f6a7b8c9d0e1] OrderService         - Order validation passed
10:30:01.128 INFO  [http-nio-8080-exec-1] [64f8a2b1c4d5e6f7a8b9c0d1e2f3a4b5|b1c2d3e4f5a6b7c8] OrderService         - Processing payment
10:30:01.128 INFO  [http-nio-8080-exec-1] [64f8a2b1c4d5e6f7a8b9c0d1e2f3a4b5|b1c2d3e4f5a6b7c8] PaymentClient        - Calling payment service for order ord-123
10:30:01.250 INFO  [reactor-http-nio-3]   [64f8a2b1c4d5e6f7a8b9c0d1e2f3a4b5|b1c2d3e4f5a6b7c8] PaymentClient        - Payment service responded: SUCCESS
10:30:01.251 INFO  [http-nio-8080-exec-1] [64f8a2b1c4d5e6f7a8b9c0d1e2f3a4b5|a8b9c0d1e2f3a4b5] OrderController      - Order ord-123 created successfully
10:30:01.252 INFO  [http-nio-8080-exec-1] [64f8a2b1c4d5e6f7a8b9c0d1e2f3a4b5|a8b9c0d1e2f3a4b5] RequestContextFilter - ← POST /api/orders → 201 (129ms)
Notice that:
traceId(64f8a2b1...) stays the same for the whole requestspanIdchanges per observation: the HTTP server span,order.create, thenorder.validate- The
doOnSuccesscallback runs on a Reactor Netty thread, not the Tomcat thread. The trace ID only shows up on that line if Reactor context propagation is on (spring.reactor.context-propagation=auto, see the WebFlux section); without it, that bracket is empty - You can look up this exact request in Zipkin by its traceId
# lessons learned from production
After running distributed tracing in production across dozens of microservices, these are the lessons that cost me the most to learn:
# lesson 1: start with correlation ids, not full tracing
Don't set up Zipkin/Jaeger on day one. Start with a correlation ID filter and MDC. That gets you 80% of the debugging value for 20% of the effort. Add full tracing once you actually need span-level detail.
# lesson 2: MDC.clear() is non-negotiable
I've seen production incidents caused by MDC leaks: a request from User A logged with User B's tenant ID, because the previous request on that thread never cleaned up. Use try-finally. Every time.
# lesson 3: structured logging from day one
Moving a running system from text logs to JSON logs hurts. Use structured logging (Logstash encoder) from the start. Future you, and your SRE team, will be grateful.
# lesson 4: don't log sensitive data in mdc
MDC values end up in every log line. Put a user's email or auth token in MDC and it's now in every log line of that request. Use opaque IDs (user IDs, not emails).
# lesson 5: sampling strategy matters
100% sampling in production means:
- A huge amount of trace data
- More network traffic to your trace collector
- A bigger storage bill
Start at 10%. If you must keep every error and every critical business flow, do it with tail-based sampling in the collector (see the performance section), since head-based sampling decides before anyone knows the request will fail.
# lesson 6: baggage has overhead
Every baggage field goes out as an HTTP header to every downstream service. Keep it small and only propagate what downstream services really need. For local-only context, use MDC.
# lesson 7: test your mdc propagation
Write integration tests that check MDC actually propagates. This one injects the asyncExecutor bean from AsyncConfig above (that's why the config exposes it as a @Bean; otherwise you'd be testing Spring Boot's default executor, which knows nothing about your decorator):
@SpringBootTest
class MdcPropagationTest {

   @Autowired
   private ThreadPoolTaskExecutor asyncExecutor;

   @Test
   void mdcShouldPropagateToAsyncThreads() throws Exception {
       MDC.put("testKey", "testValue");

       CompletableFuture<String> future = CompletableFuture.supplyAsync(() -> {
           return MDC.get("testKey");
       }, asyncExecutor);

       assertThat(future.get()).isEqualTo("testValue");

       MDC.clear();
   }
}
# lesson 8: monitor your tracing infrastructure
Your tracing setup is a distributed system too. Monitor it:
- Zipkin/Jaeger availability
- Trace export queue depth
- Dropped spans (due to sampling or queue overflow)
- Trace storage capacity
# lesson 9: use trace ids in error responses
When you return an error to the client, include the trace ID:
@ExceptionHandler(Exception.class)
public ResponseEntity<ErrorResponse> handleError(Exception ex) {
   String traceId = tracer.currentSpan() != null
           ? tracer.currentSpan().context().traceId()
           : "unknown";

   return ResponseEntity.status(500).body(new ErrorResponse(
           "Internal Server Error",
           "Reference: " + traceId  // User can share this with support
   ));
}
That way a user's bug report points straight at your trace data.
# lesson 10: invest in dashboards
Raw traces help with debugging single requests. To understand how the whole system behaves, build dashboards:
- P50/P95/P99 latency per service and endpoint
- Error rate by service
- Trace completion rate (are traces being dropped?)
- Top-N slowest endpoints
- Cross-service dependency map
Grafana + Tempo or Datadog APM can build these from your trace data.
# conclusion
In microservices, observability isn't a nice-to-have. You need it to survive on-call. Logback, MDC and distributed tracing together take you from "something is broken somewhere" to "this request failed at this point for this reason" in seconds rather than hours.
What to remember:
- MDC is the base: simple, and already built into the logging framework you use
- Always clean up MDC:
try-finallyorMDC.putCloseable(), no exceptions - Handle async propagation explicitly: MDC is thread-local, so you have to carry it across threads yourself
- Start simple, grow later: correlation IDs first, full distributed tracing after
- Structured logging pays off: JSON logs + centralized logging = fast debugging
- Micrometer Tracing is where Spring is going: on Spring Boot 3.x, just use it
- Reactive needs extra care: use the context propagation libraries instead of fighting the framework
You don't need perfect observability, just enough to debug production issues quickly and with confidence. Start with the basics, measure what matters, and improve from there.
Chỉ là những ghi chép cá nhân với hy vọng mang lại chút giá trị. Nếu thấy hữu ích, đừng ngại chia sẻ cho bạn bè & đồng nghiệp nhé!
Happy coding 😎 👍🏻 🚀 🔥.